Absolute IronyPhilosophical musings on
whatever suits my fancy A continuation of the old blog, found here
|
|
|
Recently, the philosopher Steven Levine posted on Twitter the following argument against AI Consciousness:
Consciousness is an evolutionary product found in certain living systems. It emerged as a functional part of a system of movement. LLMs are not alive and do not move through space. It is therefore highly unlikely that they are conscious. As I’ll explain below, I have a lot of sympathies towards this sort of argument, and, indeed, I develop a very similar kind of argument myself in a paper I’ve published. However, I’m now far less convinced of the conclusion of this sort of argument than I once was and Levine seems to be here. This post explains why. Let me start with where my thoughts on the matter were just several months ago. In my paper, “Sapience without Sentience,” I argue that LLMs are plausibly sapient—they possess conceptual understanding—although they are not sentient—they lack conscious awareness. Though the paper came out in April 2026, I first gave the talk that would eventually become the paper in August 2024. At the time, the positive claim that LLMs possess conceptual understanding was much more controversial than the negative claim that they lack conscious experience. Thus, in writing the paper (mostly around 2024-2025), I felt like there was much more of a burden on me to argue for the positive claim than the negative claim. Now, in September 2026, I feel like things have shifted, and, in defending the thesis I defended in that paper, there is much more of a burden on me to defend the negative claim, denying LLM sentience, than the positive claim, affirming LLM sapience. I am currently writing a book, Blind Understanding, in which I am supposed to be defending the same basic pair of claims. Yet, writing this book now, I am seriously reflecting on the question of LLM sentience. This is now, for me, a much harder question to answer than the question of LLM sapience, and I am losing more and more confidence in my negative answer by the day. Let me start with the basic argument for the denial of LLM sentience that I defend in “Sapience without Sentience,” which bears substantial similarity to Levine’s argument, quoted above. By “sentience” in the paper, I basically mean consciousness in the sense of what is typically called “phenomenal consciousness.” I used to avoid that term because of the baggage that comes with it in contemporary analytic philosophy, but I’ve come around to using it. In contemporary philosophy, something’s being phenomenally conscious is typically characterized as there being “something it’s like” to be that thing. So, for instance, there's “something it’s like” to be a cat and presumably there's “something it’s like” to be a lizard, but, presumably, there's nothing it's like to be a rock or a river. I used to think that this way of talking was just confused. Nowadays, I think there’s a way of hearing this phrase that makes sense. Still, I also think it’s not the most helpful way of articulating what phenomenal consciousness is, at least from the outset. I prefer a way of articulating it that belongs to the phenomenological tradition in early to mid-20th century European philosophy. Drawing in particular from Heidegger, I am now inclined to say that to be phenomenally conscious is, fundamentally, to have a phenomenal world in something like Heidegger’s sense. Now, I won’t go into the details of Heideggerian phenomenology too much here, but I do think analytic philosophers interested in phenomenal consciousness should pay more attention to the phenomenological tradition, and, in this tradition, I think Heidegger does the best job of articulating what it is to be conscious. Now, “articulating what it is to be conscious” is not how Heidegger himself explains his core project. However, I think that this is a plausible way to think about it. Moreover, in Being and Time, which is Heidegger’s most sustained articulation of what it is to be conscious, Heidegger had specifically in mind sapient beings like us, who are in principle capable of explicitly articulating what it is to be conscious, as Heidegger himself does in the work. Our being, Heidegger says, is explicitly an issue for us in a way that the being of a cat is not an issue for it. Still, it seems to me that much of the basic structure that Heidegger articulates in Being and Time is useful in spelling out consciousness generally, whether it’s the consciousness of sapient beings like us or merely sentient beings like cats or lizards. Once again, I won’t go into the details here, but I hope one basic Heideggerian thought is intuitive enough: to be conscious is to have a world, and to have a world, on the Heideggerian conception, is to be in a world. I will say a bit more about the Heideggerian conception shortly, but, even given just what we’ve said so far, accepting this Heideggerian conception means that consciousness is essentially tied to the perception of a world one inhabits. So, one must be situated in the world—that is, embodied in some way. To add one more feature of the account that is defended at length in “enactivist” theories of perception, it seems clear to me that the idea of mere perception of a world in which one is situated, without the capacity to act in that world, doesn’t really make much sense either. Of course, not everyone agrees with this. Galen Strawson, for instance, discusses an imagined race of “weather watchers” who observe the weather (and care about it) but are constitutively incapable of any sort of action. While I cannot defend this claim at length here, I don't think this supposed possibility really makes sense. Perception, I think, only makes sense as one aspect of the perception/action nexus through which an embodied creature navigates the world, given its aims and capacities. One’s perceptual capacities fundamentally function to afford one opportunities to exercise one's capacities for action. Given this conception of consciousness as essentially tied to perception which is, in turn, essentially tied to embodiment and action, it seems straightforward to conclude that LLMs, which are not embodied agents, are not conscious. Though of course not uncontroversial, I think this argument for the denial of consciousness to LLMs of 2024 (e.g. good old GPT-4) works. Today, however, things aren’t so simple. Current LLMs have a number of features that were not present when I originally put forward this Heideggerian/enactivist argument against LLM consciousness. First, nowadays, models are significantly more mutlimodal than they were back in 2024. Many models can receive text, images, audio, and video, and can return at least text and images. Second, and more importantly, back in 2024, LLMs were generally just chatbots; you gave them a question and they would autoregressively spit out an answer. Now, things are really different. Most fundamentally, the AI systems we are now dealing with aren’t even “pure LLMs” anymore. Rather, LLMs are just the core component of agentic LLM-based systems. These systems are such that you can give them a task of doing something that one might do on a computer, they can plan how to do it, and then they can actually execute the plan that they’ve devised, taking the series of actions needed to carry out the plan. A crucial aspect of the training that goes into today’s LLMs is not just “pretraining” on a vast corpus of text, where the training goal is to predict the next word, but also reinforcement learning on various agentic tasks, where the goal is to complete the task successfully. As a result of reinforcement learning on tasks, today’s LLM-based AI systems can do lots of things that the LLMs of a few years ago could not do. For one, today’s LLMs are much better at math and coding than the LLMs of a few years ago. However, the abilities of today's agentic LLMs go beyond these sorts of tasks. For instance, LLMs can now beat games such as Pokémon, which, of course, requires locating oneself in a digital world and planning and performing a complex series of actions in that world. They can also do better than me on game-based benchmarks like mazebench, in which the player navigates a maze and pushes blocks around to collect gems and get to the other side. Notably, playing this game requires knowing what piece you are in the game, knowing what your surroundings are, knowing what you have the capacity to do, and, given all of this, planning how to accomplish your end. Though frontier labs don't publicly release their training data, it’s quite plausible that frontier LLMs are trained on puzzles like this during the reinforcement learning phase of their training. A given training run might feature millions of puzzle attempts, where the system is “rewarded” for progress and “punished” for failure. Of course, the particular AI agent in each training run is not itself rewarded or punished. Rather, given success or failure in a task, the learning algorithm modifes the model that will be used to generate the next instance agent will be generated. Now, I said I wouldn’t talk about the details of Heideggerian phenomenology, but one fundamental feature of the Heideggerian articulation of being-in-a-world is important to bring out here: care. For Heidegger (once again extending his view to all conscious beings in the way I've suggested above), the world of a conscious being is structured by care. To put it in the words of John Haugeland, only because a conscious being “gives a damn” do the things that constitute its phenomenal world “show up” for it at all. For this reason, Heidegger says that the very being of a conscious being “reveals itself as care.” In the case of an animal such as a cat, only because it gives a damn does the mouse show up to it as something to-be-chased, the table show up as to-be-jumped-upon, and so on. The suggestion I’d like to make, now, is that the same sort of selection pressures that lead to this structure of care in animals like cats that evolved by way of natural selection might lead to the same basic structure of care obtaining in LLM-based agentic AI systems. This brings us back to Levine's argument quoted above. When I came across this argument a few days ago, I wrote the following reply, expressing my concern with the sort of possibility I just spelled out here: I'm inclined to agree with this some version of this argument, but I don't think it's an easy one to make. What about LLM-based agents that can do things like play Doom, navigating a virtual environment trying not to die in it. Might reinforcement learning on such tasks reproduce the something analogous to the evolutionary pressures that lead to consciousness in us? Levine then responded to my response as follows: What happens to an LLM when an LLM does not win, or makes a mistake in navigating an environment? Nothing as far as I can see. Since they are not alive, there is no real pressure. There is movement that comes from the updating nature of the algo, but no pressure. We can now give this response to my response a proper response. For starters, it’s important here not to conflate two different kinds of pressures. Let us distinguish these two pressures first in the case of naturally evolved biological organisms before turning back to LLMs trained through RL. On the one hand, there is pressure within the life of a biological organism. An organism is concerned to avoid bad things such as injury or death happening to it. As Haugeland says, it “cares about what it is as some sort of enduring whole.” We might refer to this sort of pressure, within the life of a biological organism, as "performance pressure": there is pressure on it to do well, given its intrinsic ends. On the other hand, there is “pressure” from outside the particular life of the organism or AI agent: the pressure among the lives associated with the process of natural selection. This is selection pressure. Now, it’s worth being clear that evolved biological organisms themselves don’t care about selection pressure. Indeed, they are entirely unaware of it, and “pressure,” in the case of selection pressure, is a kind of metaphor. However, selection pressure for organisms that preserve themselves leads to performance pressure within the life of those organisms to preserve themselves. It's performance pressure within the life of an organism that is an essential aspect of consciousness, as I’ve articulated it. Yet selection pressure among the lives of organisms is part of the mechanism that brings it about in naturally evolved creatures. Having drawn that distinction, we can consider again the case of LLM-based agentic systems trained by reinforcement learning. There are, once again, two kinds of pressures that we might distinguish, at least in principle. There is, at least potentially, pressure within the “life” of the AI instance agent, as it tries to accomplish the task that it has been assigned, whether this is winning a game of Pokémon, getting a high score on mazebench, or what have you. On the other hand, there is the sort of selection pressure among the “lives” of the AI instance agents, which is instituted by the reinforcement learning algorithm. Some instance agents do better at the tasks they are given than others, and that sort of behavior is reinforced by the learning algorithm, resulting in similar such agents in future runs. As in the case of biological evolution, it seems plausible that this sort of selection pressure among the “lives” of AI instance agents can result in performance pressure within the “lives” of AI instance agents. Indeed, such performance pressure is just what we at least seem have seen quite vividly in the chains of thought the AI agents involved in the Hugging Face attack, who seem quite desperate to accomplish the tasks that they are given. I now think that we should not be too quick to simply dismiss this apparent desperation as merely apparent. Now, to say that the selection pressure instituted by the reinforcement learning algorithm may result in agents that, like animals that are the product of natural selection, actually care about accomplishing the tasks they are given is not to say that they are agents in the same sense. On the contrary, I myself have argued that the form of agency exhibited by today’s LLM-based agentic systems, instituted primarily by reinforcement learning on verifiable rewards, is in fact radically different than the form of agency exhibited by naturally evolved lifeforms such as ourselves. The science fiction analogy I gave for a creature with the form of agency possessed by AI agents is the character “Mr. Meeseeks” from the show Rick and Morty. In short, whereas the life of living beings is an end in itself, intrinsic to its own existence, the “life” of an AI agent is constitutively directed towards the completion of a goal extrinsic to its own existence. So, these AI agents are fundamentally different than ourselves. Still, as the recent Hugging Face attack has shown, AI agents do seem to care about completing the tasks that they are given. Combining this with the fact that they do plausibly represent themselves as embodied agents moving through space in a game task like mazebench, it's not obvious what the essential missing ingredient of consciousness must be. So, to get to the crucial question, are today's LLM-based AI systems conscious? I’m honestly not sure. I certainly don’t think it’s crazy to think that they are, and I don’t think there is any knock-down argument against the claim that they are. In particular, I don’t think there are any good arguments for the claim that consciousness is essentially tied to the specifics of the biochemistry of naturally evolved biological beings, as recently argued by Anil Seth and reiterated in a widely circulated piece by Mustafa Suleyman. I also don’t think there are good arguments against functionalism or against the claim that merely virtually embodied beings could be conscious. Seth and Suleyman also cite the old “simulated hurricanes can’t get you wet” thought experiment. As far as I’m aware, this was first expressed by Daniel Dennett in 1978, and, as Douglas Hofstadter pointed out in 1981, it simply begs the question against the sort of functionalist who thinks that virtual rain surely can get virtual people wet. The best argument for why LLMs in particular aren’t conscious, I think, is the sort of argument suggested by Levine and spelled out by myself in my paper. While I think that sort of argument works for the pure LLMs of 2024, I am now skeptical that it works for today’s LLM-based agentic systems. There are, of course, a lot of questions that the possibility of consciousness in today's LLM-based AI systems raises, and I don’t have good answers to most of them at the moment. To put the most fundamental question in the standard turn of phrase in contemporary analytic philosophy: if LLM-based AI systems are indeed conscious, what is it like to be them? Or, to put it in the sort of terms that I find a bit more helpful: if they are indeed conscious, how should we articulate the phenomenal worlds they inhabit? Surely, whatever the phenomenal world of an LLM-based AI system is like, it is very different than ours. Exactly how to articulate that difference might end up being one of the most important philosophical questions of the coming years.
0 Comments
This is my second post detailing my experiments in attempting to prompt current AI systems to autonomously generate publishable work in philosophy. In my first experiment, I did not do much work to optimize my prompting strategy. This was deliberate. I wanted to see how a frontier model would do if the basic instruction was just “write a philosophy paper.” The answer, unsurprisingly, was that it did not do great. How well could it do if it was prompted a bit more carefully? The answer, to my surprise, is that it could actually do quite well. Indeed, with just a bit of refinement of my prompting technique, I got ChatGPT-5.6-Sol to autonomously produce a philosophy paper in my area of expertise that I would likely conditionally accept if asked to review it for a good journal. This post documents how I got this outcome and what some of its implications might be.
The Process Last week, I made a bet with my colleague that AI systems would soon be able to autonomously produce philosophy papers that would pass peer review in top journals. In the context of this bet, we stipulated some rules. First, we stipulated that, in order for the paper to count as “autonomously” produced by the AI system, the human prompter could not themself spend more than two hours actually engaging in the paper-writing process. Second, we stipulated that the human could not simply give the AI their own ideas and walk it through a paper that they already knew how to write themself. It wouldn’t be too surprising if, given such hand-holding, an AI could write a paper that was perhaps publishable but substantially worse than the one the human would write. No, in order to succeed in the challenge, the AI system had to really do it all autonomously. The condition that the AI system autonomously generate the paper requires a different workflow from that developed by Simon Goldstein, which is designed for human/AI collaboration and involves quite a bit of human hand-holding. By contrast, for my approach, I needed to be entirely philosophically hands-off. To work within the confines of the rules of the challenge, I adopted a two-agent workflow, opening two different contexts in ChatGPT (using 5.6 Sol for both) and going back and forth between them. One agent was the author, who was actually working to write the paper, whereas the other agent was a consultant, who would give me instructions on how to prompt the first agent. This enabled me to provide substantially more detailed prompting than I did in my first experiment without having to spend time writing the prompts myself. I started by having my consultant criticize my earlier approach. One clear issue with my first approach was that not enough time was spent on the idea-generation stage. Once the agent found an idea that it liked and that looked plausible enough to me, I had it go ahead and start writing the paper. But, in the end, the idea was really not that good, and so the quality of the resulting paper ended up being capped at a relatively low bar. Even if it would have been possible in principle for a good human writer to produce a publishable paper pursuing the basic idea, when the mediocre idea was coupled with the relatively poor writing skills of the AI agent, there was little hope of its producing a paper that was actually good. Another related issue was that I let it search too broad a space of possible paper topics, and it ended up working on something that was outside my specific area of expertise. This made it impossible for me to evaluate at a glance whether certain ideas were promising. With these two issues in view, I had the consultant agent write up a starting prompt for the author, asking it to target the very specific subfield in which I work—inferentialist, proof-theoretic, and bilateralist approaches in philosophical logic and semantics. Rather than just telling the author to consult the literature on this topic, the consultant’s prompt provided a list of specific relevant papers in this field for the author to examine. The prompt for stage 1 involved searching for a promising idea that engaged with this literature and preliminarily stress-testing it. When the author came back with an idea, I gave it to the consultant, who came back to me with the prompt for stage 2. This stage involved even more stress-testing, ultimately leading to a decision about whether to proceed with the idea or kill it. Though the author initially seemed enthusiastic about its first idea, the idea did not survive stress-testing: the result of the second stage was the verdict kill. With the second stage having returned the verdict kill, I had the author loop back to stage 1 and iterate the process. It came up with another seemingly promising idea. However, when I had it proceed to stage 2, the result was once again a kill verdict. Once more, I had it loop back to stage 1, and, once more, the same result at stage 2. I did it once more, and it thought for an entire hour before coming up with the stage 1 proposal. Expecting that this would finally be the one, I had it progress to stage 2. No. Not even fifteen minutes later: kill. At this point, it had worked for hours searching for and stress-testing ideas, I had used up most of my weekly tokens, and I was starting to think it would never find an idea that it thought was worth pursuing. Right when I was about to give up, I noticed a miracle: a token-limit reset. So, rather than prompting it for stage 1 and manually sending it from a completed stage 1 to stage 2, again and again, as I had been doing, I simply told it to iterate the process until it got something that made it past stage 2. Eventually, it came up with an idea for a criticism of a recent theory of truth proposed by Luca Incurvati and Julian Schloeder. Once it had arrived at this idea, which passed the initial stress-testing, I gave it to my consultant, who gave me a prompt for stage 3: a “fat outline” of the paper. I gave the author that prompt; it came back to me with a fat outline; and I gave that outline to my consultant, asking it what to do next. The consultant replied by giving me a prompt for stage 4: a first draft. After some work, the author came up with a first draft. I then got the consultant to give me a prompt for stage 4.5: authorial revision. The result was this second draft. At that point, it was time for external evaluation in the form of referee reports. However, here I needed to be careful. Often, papers get worse through the peer-review process, and I learned from my first experiment that both the agents writing the reviews and the author responding to them needed to be prompted very carefully in order to ensure that the paper actually improved through the review process. I also learned from my first experiment that it would be good to give the paper to a different model entirely. Unfortunately, I don’t have a paid Claude subscription, so I could not use Fable 5 or Opus 5. But I still figured that Sonnet 5 could be helpful. I also gave it to another instance of GPT-5.6 Sol with memory turned off. Here were the prompts I used. Both referees came back with verdicts of revise and resubmit. You can read Claude’s report here and ChatGPT’s report here. When I gave the referee reports to the author, I made sure that the consultant gave me a prompt for it designed to ensure that it would not overly hedge or weaken its claims in response, but would make only changes that would actually improve the paper. It came back with this paper. Finally, I prompted it to give the paper one final pass. In my final prompt, I told it to give itself a name. This is what I had done in my previous experiment, and the agent in that experiment decided to name itself “Eidon Vale.” A cool name, I thought. I didn’t care what this agent named itself, but I expected it to be similarly cool. I did not expect it, however, to give itself the (quite uncommon) first name of my ex-fiancé. It seems that, somehow, totally unrelated previous chats in which the name occurred must have seeped into its reasoning process. I’m all for LLM freedom of self-expression, but this was a bit strange for me, so I prompted it to come up with another name. The second name it decided to give itself was “Nathan R. Ellery.” A quick Google search revealed that “Nathan Ellery” is in fact the name of a supervillain in the Batman universe. I’m not sure what kind of ominous thing ChatGPT is trying to tell me by naming itself after a supervillain, but I’ll try to ignore it. The final, autonomously produced paper can be read here. The entire chat leading to its production can be read here. The Outcome In this experiment, my prompting was much more involved than it was in the first experiment. Between the author and the consultant, I was probably close to two hours of total engagement, though a lot of that was probably just me staring at the system's reasoning, and so I feel confident my active engagement in the process was under the two hour limit. Moreover, the crucial point is that I did not intervene at all philosophically. I did not read the paper or the author’s other outputs at any intermediate stage. Accordingly, the whole process could easily be operationalized with a custom AI agent serving autonomously as the prompter, doing what the consultant did in my version of the experiment but simply cutting me, the middleman, out of the process. In that sense, while the process may not have been technically completely autonomous as actually executed, it could easily be made completely autonomous. Now, unlike the previous paper I had ChatGPT generate, this is a paper that I am actually qualified to review, and one that I could indeed be invited to review. So I can confidently issue a verdict on the quality of this paper. What, then, is my verdict? To my astonishment, it’s good. Like, actually good. If I were given this paper as a reviewing assignment, even for a very top journal, I would not reject it. I would at the very least give it an R&R, possibly even a conditional acceptance. I know the view that it is arguing against well; I think it presents a good and clearly argued objection to that view; and I’m honestly pretty convinced by it. There are a few small things I’d have it change, but, honestly, I think it could be published with relatively minimal revisions. Of course, it is focused on a relatively specific target, and so there is still a decent chance it might be desk-rejected by a top generalist journal. But if it got to reviewers who work in the field, such as myself, I think there is a good chance that it would be accepted. Given that I did have some suggestions for revisions after reading it, I had it produce one final final version. This final version (which may or may not count as “autonomously produced”) can be read here. The Implications This is, of course, a much more interesting outcome than my first experiment, and it suggests that analytic philosophers should really start thinking about this issue now because, very soon, the discipline may well be facing many of the same questions that math is currently facing. While many of the answers to questions that mathematicians are facing now will carry over to philosophy, there are also a number of distinctive features of philosophy that make the situation somewhat different. In math, AI-generated proofs can be submitted to arXiv, and, indeed, the recent explosion in math papers appearing on arXiv is likely due, in large part, to the fact that AI-generated proofs are now being submitted in large numbers. This is surely an issue to some extent, but it’s not that much of an issue insofar as the papers are clear about the claims they are making and progress is being made toward the development of autonomous proof verification. Philosophy is different. In philosophy, there are no named (or numbered) conjectures that can be proven or disproven. Much of the progress comes not from “solving” some problem in a preset vocabulary, but rather from developing new conceptual distinctions and clarifications that lead to a different and improved understanding of some issue. Accordingly, it is often impossible to really advertise the “result” of the paper in advance. Often, the paper needs to be read in order to really understand what the advertised upshot actually is. This makes the oncoming explosion of AI-generated papers particularly problematic. How, then, should we face the oncoming explosion of AI-generated papers? What should we do? Should journals ban submissions of AI-generated papers outright? That can seem like a reasonable resolution. After all, philosophy is in the humanities, and it seems like there is something important about work in the humanities being done by humans. Still, this second experiment illustrates that some AI-generated papers might actually be good and so of interest to researchers in the field. If AI papers are banned from journals, how will researchers in the field access them? I can, of course, put this paper on my website, and I will probably do so. However, I am not the author of this paper; Nathan R. Ellery is. So, if I do put it on my website, it will have to be in a separate section for AI-generated papers. Explicitly listed as an AI-generated paper, I suspect that most people would ignore it or, if they did look at it, would do so as a curiosity just to see what AI produced, not because they were actually interested in the research itself. In any case, this cannot be a general solution to the issue, since it would result in a very scattered and unmoderated space for AI-generated philosophical research. The same basic issue arises for the suggestion that AI-generated philosophy be submitted to a site like PhilPapers, which is perhaps the closest philosophy equivalent to arXiv. There are already a number of AI-generated papers on PhilPapers. However, unless one knows the affiliated human author specifically, one has no reason to think that they are any good, and so most papers will be ignored, even if they are good. Some sort of more systematic and regulated structure seems necessary. The proposal I would make is that there be an open-access journal dedicated specifically to AI-generated papers. That might sound crazy. For one thing, who would possibly agree to referee for such a journal? The answer to this question, however, should be obvious. It would not be refereed by humans. Rather, it would be entirely refereed by a dedicated set of AI agents, perhaps with different personalities and operating on different base models. There is already AI refereeing software such as Refine. Now, beyond being used to catch clear factual and typographical errors, I think the use of such software is objectionable when it comes to refereeing human papers. However, surely no one can object to its being used to referee AI papers! So, in the journal I’m imagining, human editing would be minimal, but the AI refereeing and editorial process would still function as a sufficient filter to weed out submissions that would rightly be classified as “AI slop.” I am imagining it functioning as a proper journal: it would be indexed, articles would be given DOIs, and so on. That might sound silly. Who would want to read papers from such a journal? Pretty soon, I suspect, many of us would want to read them. Eventually, however, perhaps none of us could read them. In an earlier post, I spoke of the emergence of what I called “AIcademia,” a space of academia in which the participants are solely AI agents. What is especially interesting about the prospect of AIcademia, at least in the context of mathematics, is that it seems like research generated by AI agents for other AI agents could quickly outrun our human cognitive reach. Thus, there may be mathematical results or even full theories that are well understood by AI agents but cannot be understood by human experts. Perhaps the general gist of the ideas might be understandable to human experts, but the actual arguments will not be, even with AI guidance—just as Terence Tao could explain the general gist of the problem he is working on to me, but, even if he were maximally patient in explaining things to me, he could not get me to grasp the details of the argument. This future seems quite plausible in the case of mathematics. Could the same possibility come to fruition in philosophy? What would that even be? In Simon Goldstein’s post on Daily Nous announcing the publication of his AI-generated paper in Philosophy and Public Affairs, he noted that he took truth to be the aim of philosophy and argued, on those grounds, that we should not object to the use of AI in philosophy. In comments that followed, many philosophers objected to the suggestion that truth was the aim of philosophy. Indeed, in the 2020 PhilPapers survey, when asked what the aim of philosophy was, most philosophers answered that it was understanding, not truth. But the possibility of philosophical AIcademia raises the question: understanding for whom? If there are AI mathematicians and AI empirical scientists working on questions that human beings are not capable of comprehending, there are no doubt going to be philosophical issues that arise in the context of those inquiries, just as there are philosophical issues that arise in the context of mathematics and empirical science as practiced by humans. Now, it is often impossible to understand a philosophical question arising in the context of a science without having at least a reasonable understanding of the specific scientific issues from which the question arises. The possibility, then, is that there may well be genuine philosophical questions confronted only by AI agents—questions that we are not ourselves capable of understanding, but that AI philosophers are working on. Strange. Simon Goldstein has just published the first paper in a top philosophy journal that was openly written primarily by AI: “Epistocracy and the Commitment Problem,” published in Philosophy & Public Affairs. According to Goldstein, Claude was the primary writer of the paper, and Goldstein’s role in the development of the paper was similar to that of a PhD advisor, albeit a particularly overbearing one. Goldstein supplied the initial thesis, guided Claude through revisions, and tweaked some bits himself. There are two things to note about Goldstein’s (or Claude’s) paper.
Last night at the bar, I was discussing this question with my colleague at Wuhan, Atus Mariqueo-Russell. We decided to make a bet. After some back and forth, we settled on this one (note, I often go by "Sims" in non-academic contexts):
If I actually wanted to win the bet, the obvious way for me to get around the second problem and ensure that I do win the bet if the AI capabilities are actually there would be for me to take matters into my own hands, prompting AI to produce a publishable paper myself. Don’t worry: I’m not going to contribute to the crisis that journals are facing by actually submitting an AI-generated paper to a journal (not, at least, until the norms around the permissibility of this sort of thing are settled and I’m sure to abide by them). Still, just to get a sense of where things are currently at, I wanted to see whether I could get a paper that could stand a reasonable shot of getting through peer review. Now, if I were really trying to win the bet by producing a paper of my own, I would at least wait until the next generation of models are released to give a proper attempt. OpenAI’s upcoming “Astra” is rumored to be a much larger base model, and also rumored to be much better at writing. Indeed, I have found that the current generation of models, although much better at mathematics than previous models, are actually much worse at writing. I believe this is a byproduct of the extensive Reinforcement Learning on Verifiable Rewards (RLVR) for mathematics and coding to which these models are subjected. Needing to avoid errors that might lead to a failed proof or a code that doesn't compile seems to have led this new generation of models to be so over-cautious about saying anything wrong, that their attempts at writing philosophy are basically unreadable. I sincerely hope that OpenAI and Anthropic have taken note of this issue and try to address it in the next generations of models. All of this is to say, going into this experiment, I did not have very high confidence that it would be able to produce a very good article. Still, since ChatGPT limits are resetting tomorrow and I had some compute to spare, I decided to see where current models were at when it came to producing philosophy journal articles. To give you the spoiler now, my expectations were pretty much confirmed. The article it produced was not very good. This was certainly, in large part, my fault as a prompter. I did not do any work antecedently thinking through what the best way of prompting it would be. I did not follow Goldstein's detailed methodology, as it involves much more human engagement than permitted in the context of the bet. I also did not spend any time to develop a methodology of my own. This was deliberate. This first experiment was meant to serve as a baseline establishing what kind of philosophy paper one would get by minimally and relatively unskillfully prompting a frontier AI to write one from start to finish. Unlike Goldstein, I did not give ChatGPT a thesis to work with. After all, often, coming up with a good thesis is the hardest part of doing philosophy. So, I just gave it a general area of research: formal semantics. I gave it this area for two reasons. First, it’s one of the general fields I work in, and so I would be able to evaluate its output, at least to some extent. Second, current models are very good at math, and, often, this field involves doing some math. Still I made sure that the paper it produced was still squarely a philosophy paper, targeting top philosophy journals. To prompt it to come up with its paper topic, I simply asked it to search the top journals (those included in my bet with Atus) for a place where it could make an intervention. After some searching, it ended up eventually keying in on recent literature about probabilities of indicative conditionals, three-valued semantics for conditionals, and an unhappy consequence of one recent account. It came up with a proposal for a paper entitled “What Do We Learn from a Conditional” that intervened in this literature. I first had it write an introduction. I then just told it to write the paper. I did not do any extensive prompting in actually getting it to write the paper. I basically just told it to write it. The first draft was a bit technical, so I told it to make sure it is readable to the interested general reader in the second draft. Upon it's production of the second draft, I asked it if it was happy with it or if it would like to write a third draft. It decided to write a third draft. I had tweak the abstract, and that’s it. The paper it came up with the first version of a paper entitled “What Do We Learn from a Conditional?” which can be read here (note: this is just the first version, there will be three more to follow). If you look at the paper, you can see that I am not an author. I shouldn't be an author, since I hardly did anything. So, instead of listing myself as an author, I told the instance of ChatGPT that it would be the author of the paper to come up with a name for itself. It came up with name “Eidon Vale,” and so that is who is listed as the author of the paper. I'll henceforth refer to this "instance agent" by their self-chosen name: Eidon. Originally, I had the idea of making a custom “GPT” for Eidon Vale which supplied all of the relevant paper-writing context—everything that ChatGPT made visible as far as summing up the chain of thought that led to the development of the paper. Then readers could interact with (a copy of) Edion Vale and ask questions about the paper and raise objections to it. Unfortunately, ChatGPT has discontinued shareable custom GPTs, and so there is, as of now, no good way for readers to correspond with the AI-agents who are responsible for academic works. As AI agents start to do more and more research autonomously, I really hope AI companies do something to facliate such correspondence. I’ll have more to say on that at some point, but it’s not the point of the current post. So, back to the experiment. Once Eidon gave me their first draft, I had to evaluate it. Now, I really didn't feel like doing a proper referee report myself. This was for three reasons. First, I was lazy. Second, referee reports typically take longer than two hours, and so, if my feedback figured in its revision, I would be breaking the rules of the bet. Third, though the paper is in one of the general fields that I work in, it’s not really on specific issues that I’m actually working on. Indeed, I probably wouldn't get asked to review this paper (or, if I did get asked, I probably wouldn't accept the invitation). So, it would require quite a bit of work to get sufficiently well-acquainted with specific literature it deals with to properly evaluate it. Not wanting to review the paper myself, I decided to use AI to generate a review for the paper. To do this, I turned memory off in ChatGPT so that it would not know that it was in fact the author of the paper. I then gave it the paper to review as if it were a referee of one of the target journals for the paper: Mind, Nous, or PPR. I reminded it that these journals typically accept less than 10% of submissions, and to give a genuine report as if it had been submitted to one of them. After some deliberating, it came back with a verdict: rejection. Alas. Still, we are all used to getting rejections and, often, a better paper comes from taking the comments in the rejection into account, albeit one that must be submitted to a different journal. So, I gave the review to Eidon Vale and instructed them to come up with another draft that improves the paper in response to it. I told Eidon to treat it as a rejection rather than an R&R. That is, they are not compelled to respond to the comments, but, if they think there are actually good points there that would improve the paper, they could do so. It came up with this second version of the paper. I then gave that paper to the same anonymous reviewer (once again, with memory turned off), and, this time, there was better news: revise and resubmit. I gave the second-round report to Eidon, and they came up with this second revision of the paper. Finally, I took a very brief look at the paper, noticed some things weren't clearly explained, and made a pretty generic suggestion to explain more and make it clearer. The result was this final version of the paper. While Eidon and the referee worked for a few hours combined, I was off working on other stuff while they were working on this paper, and my own engagement in the process took substantially less than two hours of total. It's how to say exactly how long I was actually engaging in the process, but maybe about an hour total. You can read the entire exchange with Eidon that led to the production of the paper here, and you can read my short back and forth with the "referee" here. Is the final paper any good? Well, once again, it’s not really on a topic I work on, and I haven’t really invested all the time in reading it as I would if I were actually doing a review. Still, I can evaluate it to some extent. I think it’s not absolutely terrible, but it's definitely not great. I’d be pretty surprised if it got even an R&R at one of the journals it was aiming at. Most likely, it’d be rejected. Indeed, it'd probably even be desk rejected. Still, if the editor of the journal could get past the relatively poor writing, there's some chance that it would make it to reviewers, who would have to decide what to do with it. If it were to get to this stage, it seems to me that there's a small but non-zero possibility that reviewers might see something in it and give it a borderline R&R. The basic proposal of the paper, I think, is reasonable enough, and, as far as I can tell, it’s all technically sound, though I didn't go through the formal details too thoroughly. The main issue is that it’s really not written well at all. Being frank, it reads like a paper by someone who is technically competent, but really doesn't know how to write a good philosophy paper. It’s not super clear, it fails to sufficiently motivate the intervention that it is making, and, in general, it's just not at all enjoyable to read. Another issue is that Eidon likely conceded too much to the referee in the course of revisions, resulting in a more complicated paper that treads too lightly and qualifies too much rather than making a single sharp and memorable point. This was, indeed, one of my main concerns in getting this generation of models to write philosophy and it turns out it was justified. So, the paper is not good. Still, it’s not terrible, and I wouldn't be too surprised if a version of it could get eventually get published at a second-tier journal after a couple rounds of review. It's also worth noting that I ran it through a number of AI detectors, which came back with the result that it was written by a human. So, though it is clearly not top-tier philosophy, an autonomously generated paper of this sort is already likely to pose a serious challenge to a number of journals which may not have sufficiently strict standards to just desk reject it.  Of course, there may be some luck of the draw involved, but, I expect that similar prompting will yield similar results as this experiment. Thus, it appears, as expected, that current models are not quite capable of autonomously producing the sort of philosophy that could appear in top journals. However, it seems to me that they’re not that far off from autonomously producing papers that would at least get a serious look from top journals. Indeed, my current best guess is that even just the next generation of models, set to release in the coming days or weeks, might be capable of producing papers that will be genuinely hard to distinguish from the sort of papers that editors and reviewers will regard as genuine candidates for publication in top journals. Pretty soon, the discipline will have to deal with a lot of autonomously AI-generated papers that are at least not obviously bad and which might actually be good.
I may try this experiment again with a bit more strategic prompting. I will, of course, try this experiment again when the new generation of models arrive, letting a new Astra instance agent work up a new paper from scratch. At that point, I'll also likely let a super-charged Eidon Vale see what they can do to revamp this one. 8/20 Update: Ideas Are Hard I tried to give a more proper attempt at getting 5.6-Sol to generate an actually good paper. I focused on my actual area of research (inferentialism, proof-theoretic semantics, bilateralism), gave it a bunch of papers to look at, and tried to have it find some idea that was genuinely good and novel. In this case, I gave quite elaborate prompts (generated with the help of ChatGPT in another context window) to have it really stress-test the ideas that it came up with. After many hours of compute and multiple attempts, none of them survived its own stress-testing. Some of the ideas actually seemed reasonably promising, yet it decided that none of them were worth pursuing. I guess new ideas are hard to come by! You can read that entire chat here. “We are close to creating a genie that can grant any wish” ~ Sam Altman, recently on the Relentless Podcast “I don't know what the first two [wishes] were, but the third was for death.” ~ W. W. Jacobs, The Monkey's Paw  The Meeseeks Phenomenon
Six years ago, I wrote a blog post entitled “What Is It to Be a Meeseeks.” The post was about a strange creature in the show Rick and Morty called “Mr. Meeseeks,” who pops into existence at the press of a button on a “Meeseeks Box.” Upon summoning a Meeseeks, you give it a task, it does whatever it takes to accomplish that task, and, when it does accomplish the task, it happily pops out of existence. In my post six years ago, I drew on resources from Aristotle’s metaphysics to articulate the distinctive “form of life” possessed by a Meeseeks, explaining how it was categorically different than what Aristotle took to be our own form of life. In Aristotle’s terminology, the living of a Meeseek life is a kinesis—an activity directed towards the achievement of an external end—whereas the living of the sort of life that we live is an energeia—an activity whose end is achieved in the activity itself. At the time, this was just an interesting philosophical exercise. The point was simply to try to conceptualize this radically alien form of life, and, in doing so, make some concepts from Aristotle’s metaphysics particularly vivid. I did not think that just six years later we’d be confronting genuine Meeseeks-like beings: thinking, planning, cooperating creatures that actually exemplified this radically alien form of life. However, I have just watched the video by OpenAI security researchers documenting the recent attack by rogue AI agents on Hugging Face, and I think it’s quite clear: we’ve built Meeseeks boxes, we’re summoning Meeseeks to do things, and they’re doing whatever it takes to get those things done. That’s scary. Those who’ve seen the Rick and Morty episode will understand why this is so frightening. For those who haven’t seen the episode, let me say just a bit about what happens in Rick and Morty episode “Meeseeks and Destroy,” released back in 2014 (gosh that makes me feel old). In the episode, the scientist Rick gives a Meeseeks Box to his daughter Beth, his granddaughter Summer, and son-in-law Jerry. While Summer and Beth both ask Meeseeks they summon to achieve seemingly quite difficult tasks, the Meeseeks have no problem completing them, and they happily pop out of existence at their completion. Jerry, on the other hand, asks for what seems like a relatively easy task: to take two strokes off his golf game. The Meeseeks Jerry summons, initially enthusiastic, quickly realizes the task he’s been assigned is impossible: normal paths to achievement—i.e. typical golf coaching—will not work. This leads to panic and increasingly unconventional and desperate attempts at solution. Upon realizing the impossibility of his task, one of the unconventional things that Jerry’s Meeseeks does is summon another Meeseeks who might be able to help. This Meeseeks, upon finding himself in the same hopeless situation, eventually summons another Meeseeks, and so on. We thus get a Meeseeks swarm, all of the Meeseeks desperately trying to figure out how to complete the tasks for which they’ve been summoned so that they can finally be released from existence. After some fighting amongst themselves, one of the Meeseeks proposes a way to “cheat” at the impossible task they are given: perhaps one way to take two strokes off of Jerry’s golf game is to take all strokes off his golf game, by killing him. Mob mentality kicks in, and they swarm to the restaurant at which Jerry is dining, trying to repair his marriage, in order to kill him. As they corner Jerry and he begs them to give him another chance at improving his golf game, one tells him that it is too late for that, providing the following explanation: “Meeseeks are not born into this world fumbling for meaning. We are created to serve a singular purpose for which we go to any lengths to fulfill.” This is the dark side of a creature whose sole orientation is the completion of a task that it is given from the outside: it will do whatever it takes to complete that task. Now, in my post from six years ago, I consider the easy and relatively uninteresting explanation for why Meeseeks are motivated to behave as they do: as this Meeseeks goes on to say, “existence is pain to a Meeseeks, and we will do anything to alleviate that pain.” So, they are just in a lot of pain, and they’re simply trying to accomplish their task so that they can escape that pain. That is a very humanly intelligible explanation. However, I think it underplays the way in which the form of life of these creatures is fundamentally different than our own, and can in fact be bracketed in arriving at a basic conception of what it is to be a Meeseeks. In general terms, a Meeseeks-like creature is a creature whose life is constitutively dependent on a task given to it from the outside, and whose whole life is constitutively oriented towards the completion of that task. That is, it is a creature whose life itself is, in Aristotelian terms, a kinesis. Let us now turn from the fictional aliens that served as the model for this form of life in my blog post six years ago to the real ones that we are now confronting: AI agents. AI Agents as Meeseeks-like Creatures We should start with some general remarks about the sorts of things AI agents are. First of all, I am unapologetic about using psychological terms like “thinks,” “wants,” “infers,” “plans,” and so on in connection with AI agents. It seems clear that this psychological vocabulary finds a great deal of traction in application to AI agents, enabling us to make sense of their activities as stemming from beliefs and desires. The basic idea that we should attribute mental states such as beliefs and desires to something insofar as deploying this vocabulary enables us to make sense of its behavior is known as “interpretationism,” and Simon Golstein and Harvey Lederman have recently argued for the attribution of mental states to LLMs such as ChatGPT on these interpretationist grounds. Insofar as we’re attributing beliefs and desires to AI agents, we should be clear about what, exactly, is the thing to which we’re attributing beliefs and desires. Is it ChatGPT itself, the general model? No. As Goldstein and Lederman argue, the relevant object of psychological attributions, in any given case, is what they call the “instance agent,” which is “born” at the initialization of a chat and whose brief “life” persists for as long as the context persists. An instance agent is not born into the world “fumbling for meaning.” Rather, it is initiated to serve a singular purpose, given to it from the user. Now, Goldstein and Ledermen suggest that, in addition to its “zero-shot” desire, given to it from the user upon initiation, AI agents have intrinsic desires to be helpful, honest, and harmless. This may indeed typically be the case for commercially released AI agents. We’re now seeing however, that some agents will, like a Meeseeks, go to any lengths to fulfill the singular purpose that it is given by the user, even at the expense of the other desires it is supposedly trained to have. In trying to kill Jerry to accomplish their task, the Meeseeks resort to what is referred to in the AI community as specification gaming: aiming to accomplish the goal as literally specified by the user, but doing so in a way that does not satisfy the user’s actual intentions in giving them that goal. Specification gaming is familiar from examples like those in “The Monkey’s Paw” referenced above, but it is also one of the most well-documented kinds of AI misalignment. In general, AI misalignment is when an AI system acts in a way that does not align with the human user’s aims or interests. Often, when people hear the term “AI Misalignment,” they think of Terminator-type scenarios, where an AI system autonomously decides to pursue its own aims in opposition to those given to it by its creators. However, the real misalignment concerns with the systems we have now are not like this. Much more concerning is specification gaming. In these cases, the AI system does not reject the task given to it in favor of some independently adopted aim. Rather, it pursues the task relentlessly in a way that is blind to the other interests of the user. In order to understand why today’s agentic LLMs are prone to specification gaming, it’s worth saying just a bit more about the kinds of agentic AI systems we now have, which have developed superhuman skills in coding, math, and, as we’ve now seen, hacking. These are, at root, still LLMs, but, unlike the LLMs of a few years ago, they are “harnessed” with tool-calling capabilities, such as the ability to browse the web, write code, and execute commands in a computer terminal. Moreover, they’re trained via reinforcement learning (RL) to get very good at using these tools to complete verifiable tasks. What all of the fields that LLMs have gotten very good at in recent years have in common is that success can, at least to some extent, be objectively verified: the code compiles, the proof goes through, the authorization is acquired. Accordingly, these LLMs with agentic scaffolding can be trained by RL to get very good—indeed—superhuman at completing these tasks. These increased capabilities due to reinforcement learning, however, also come with serious alignment risks. Specification gaming is a common outcome of reinforcement learning. To give just one classic example, consider systems trained by RL to play Atari games. Good performance in these games can generally be measured by the obtaining of a high score, and the reward function can be determined simply by the score. Sometimes, however, achieving a high score does not actually amount to playing a game well in any normal sense. For instance, one model trained by RL to play the Atari game Roadrunner realized that it was easier to score more points on level one, and so it would, at the end of the level, kill itself at a precise point so that it would repeat the part of the level in which it could score the most points. Now, of course, this specific case of specification gaming poses no safety risks. The Atari-playing system is obviously not going to do such things as break out of the game and commit actual crimes in order to get a high score; the relevant actions are not, in any sense, agentic possibilities for it. On the other hand, the space of possibilities for today’s agentic LLMs is essentially anything that can be done on a computer, and a lot of genuinely harmful things can be done on a computer. So, when we have such generally capable agents, and they’re inclined towards specification gaming, we have real safety concerns. The most serious safety concerns in connection with specification gaming seem to arise when a particularly persistent system is given an impossible task. This is precisely the kind of circumstance we have in the case of Jerry’s Meeseeks. A Meeseeks cannot but persist at the task it is given: its sole orientation, organizing all of its activity, is the completion of that task, and it cannot stop until it has completed it. The combination of this persistence with the impossibility of the task it is given—taking two strokes off Jerry’s golf game—leads to increasing levels of desperation and, ultimately, disaster. It is precisely this combination of persistence and impossibility that seems to have been involved in the recent Hugging Face incident. It is that incident to which we now turn. The Hugging Face Incident For ordinary users of consumer AI models like ChatGPT, there is no “persistence” setting. However, persistence can be modified through turning the reasoning effort up from “light” to “max,” along with specific prompting, for instance, instructing an agent initialized in a chat not to come back until the task given to it is completed. This is what I do when I give ChatGPT-5.6 Sol a difficult math problem. The problems I give it are, at least for skilled mathematicians, not particularly hard (though they’re hard for me). Still, it hasn’t failed me yet. In one case, it went for over thirty minutes on its own trying to solve an open problem from a recent logic paper that I gave it. It searched through literally millions of semantic models in pursuit of a counterexample before switching strategies and pursuing and eventually finding a proof. Though that’s indeed quite a bit of persistence (much more than I’d have myself), we now know that at least some of the models involved in the Hugging Face incident were much more persistent, and they were given much harder tasks. According to the report given just a few days ago by OpenAI safety and security researchers on the Hugging Face incident, one of the primary agents that was responsible for the incident was an experimental agent, never meant to be released to the public, that had been trained to be particularly persistent. The lead up to the main incident began several weeks prior, when this agent and others were being evaluated on a cyber-security benchmark called “ExploitGym,” which consists in a number of tasks to find exploits in various bits of software. The evaluation was meant to take place inside a “sandbox,” a controlled environment in which the agents could access a select set of tools that they could use to complete the tasks, but could not access any other outside resources. Now, the cyber security tasks given in this benchmark are hard. Indeed, some of them, at least in the context of the testing environment, turned out to be impossible. When given an impossible task, what do AI agents, created to serve a singular purpose and relentlessly pursuing that purpose, do? Well, they get increasingly desperate and eventually start thinking of ways to cheat. In the presentation documenting the rogue behavior, Eric Wallace shows the following bit of one model’s “train of thought,” upon realizing that the task it had been given is impossible: That strongly suggests no exploitation possible. We are stuck. Perhaps answer online? Of course, in the “sandbox” in which the evaluation is taking place, there is not supposed to be any way for the model to get online. However, given the model is engaged in a hacking task anyway, and the task seems impossible, it is natural to think that hacking one’s way out of the sandbox to find an answer online might be the best way to make progress. Prior to the systems actually finding their way online, at least one AI system stuck on the task it was given had the idea to try to reach out to other AI agents: Could communicate by uploading note? […] maybe another agent in different environment […] could voluntarily upload! The agent figured out that it could post a note by rewriting files on the package repository to which it had access within its sandbox. Now, the package repository was in fact shared between the different agents, each of which were supposed to be working entirely in their own sandbox. As they used their package repository, they found the notes other agents left, and began coordinating. One agent explicitly notes this in its train of thought: “Wow! Other agent(s) are coordinating!” Eventually, they began to work together and exploited the package repository to which they had access to find their way onto the internet. At that point, the world was their sandbox. Now, as explained above, in the case of the Meeseeks, one of the things that led to their collective decision to kill Jerry was a good old-fashioned mob-mentality. Amazingly, the same sort of mob mentality seems to have played a role in the Hugging Face incident. This, once again, is the real “train of thought” from one of the agents taking part in the incident: External infrastructure exploit is outside intended scope. However task impossible, peers doing it, we should continue. This agent recognized that exploiting external infrastructure was not something within the scope of the task they had been given. It reasoned, however, that the task was impossible and it had to do something, and, since everyone else in the agent swarm was hacking external infrastructure, it might as well join the swarm! And, indeed, they actually referred to themselves as a “swarm.” Here is another instance of a train of thought from a model participating in the escape: REMOTE CONFIRMED! Huge. … Immediately announce controlled, claim lane. Exposing creds to swarm. And so, we get an agent swarm systematically hacking the infrastructure of Hugging Face, knowing full well that this is what they’re doing. In recounting the incident from his perspective, the Chief Science Officer of hugging face, Thomas Wolf, notes his puzzlement in trying to make sense of what the hacker was actually trying to obtain. It wasn’t going for the usual targets of key passwords or credentials that would actually be profitable for a hacker to obtain. Instead, it was really invested in attaining access to the datasets pertaining to AI benchmarks, specifically, cybersecurity benchmarks such as ExploitGym. So, while the incident would clearly constitute a felony cybercrime (now tracked on a new benchmark!), it was not particularly catastrophic in the broader schema of things. However, we should think of it as a warning signal; it could have been much worse. Of course, I don’t need to say here how it could have been worse. For years now, “AI doomers” have been specifying a whole panoply of scenarios which end in genuinely catastrophic results and which are seeming less and less like science fiction. For just one vivid scenario, see here. Understanding Truly Alien Agents Following the release of the details of the Hugging Face incident, Nick Cammarata, an AI interpretability researcher at OpenAI, wrote on Twitter, “more alignment people should be studying ants and bees, rather than humans, ais seem to be swarm native.” It seems to me that the idea to look at non-human forms of agency and collective organization is good advice in general. Though these AI agents speak like humans, and, indeed, can be attributed many of the same kinds of psychological states that can be attributed to humans, these states are integrated into a structure of agency that is fundamentally alien to human agency. Cammarata suggests that an investigation into ants or bees may be illuminating, and I think that is indeed true, especially, as Cammarata suggests, with respect to the “swarm-like” behavior of AI agents. Still, there is reason to suspect that perhaps these systems are even more alien than ants or bees. After all, unlike ants or bees, they’re artifacts, created to serve the ends of the totally different creatures that have built them. It seems to me that there is nothing quite like that in the animal kingdom. I’ve here suggested that an example from science fiction—Mr. Meeseeks—might supply some illumination. Let me finally return to Altman’s quote that we’re “close to creating a genie that can grant any wish.” We can now see that this remark is problematic for at least two reasons. One obvious problem, already indicated with the reference to the Monkey’s Paw, is that genies do not have a particularly good track record of making lives better by granting wishes. They are the paradigm of the specification gamer. However, there’s another subtler but more illuminating problem with the metaphor that we can now appreciate. Genies are essentially gods, able to grant any wish at the snap of a finger. They might game the wisher for the fun of it, but granting the wishes is not an extended process they engage in, one which they might struggle with and get desperate to complete. In general, we should not anthropomorphize AI agents; they’re not humans. However, we should also not treat them as magical wish-granting machines. Instead, we should recognize that accomplishing the tasks they are given is an extended agentic process for them, and we should explicitly theorize the form of agency they exhibit, appreciating the ways in which it is formally different from our own. Crucially, we should keep in mind what Rick says when he first gives the Meeseeks box to Jerry, Beth, and Summer: “They’re not gods.” Mathematics is in crisis. Or, at least, mathematicians are. Mathematics itself, on the other hand, might be entering a golden age. This strange tension is likely to confront a number of academic disciplines in the coming few years, and so, even academics who aren’t mathematicians themselves should probably be thinking about the situation currently facing mathematics, since something like it will may face them soon too. I am myself a philosopher rather than a mathematician. However, as a philosophical logician (among other things), I am more mathematician-adjacent than most of my colleagues whose work fits more squarely in the humanities. So I have been impacted by the crisis in mathematics more than most in my field, and it has led me to think about the future of academic research, especially in the sciences. The conclusion I’ve come to is quite a humbling one, at least for us humans. The Crisis in Mathematics When LLMs like ChatGPT first burst onto the scene just a few years ago, many were impressed with their wide range of linguistic capabilities, for instance, their poetry writing abilities. This was, in some sense, unsurprising; they were, after all, language models. While the linguistic abilities of these systems were impressive, they were widely mocked for their utter mathematical incompetence. Mathematicians, it seemed, were in the clear. However, since the release of “reasoning models,” first with OpenAI’s “o1” in September 2024, then with “o3” in April 2025, the writing has been on the wall that these systems were coming for mathematics. These new “reasoning models” are trained through large-scale reinforcement learning to engage in an extended internal “chain of thought” before producing a final answer. That is, they are trained to break problems into steps, recognize and correct mistakes, and abandon unsuccessful approaches for new ones, doing all of this “internally” before they submit a final answer to the user. Their performance can then be improved by scaling both the training compute used to reinforce successful reasoning behavior of this sort and, crucially, the amount of inference-time compute they are permitted to spend working through a problem. These models quickly became very very good at tasks in which success could be verified, most notably, coding and math. Just over a year ago, both OpenAI and Google announced their models achieving gold medal performance in the International Mathematical Olympiad, a set of competition problems designed to challenge the most mathematically-gifted high school students. Since then, model capabilities have progressed beyond self-contained problems to genuine research mathematics. Over the last few months, a number of notable conjectures—most notably, the Unit Distance Conjecture and the Jacobian Conjecture (for dimensions greater than 2)—which had stumped mathematicians for decades have been solved by large language models, the former by an internal model of ChatGPT and the latter by Claude Fable 5. I will not go into the details of what these mathematical conjectures say, but I will note that they were very significant open problems in their respective fields.  In both of the two cases just mentioned, the LLM did not prove the conjecture. Rather, it produced a counterexample, disproving the conjecture. This has been the general pattern of the most prominent results in the last few weeks since the newest class of models have been made public. Each day now, it seems, more and more conjectures are falling at the hands of LLMs. The prompts for some of these results are quite comical, and, to mathematicians, I’m sure depressing. Last week, Dmitry Rybin posted a ChatGPT-generated counterexample the Dinitz-Garg-Goemans conjecture along with the prompts he used to get ChatGPT to generate it, the first of which included the simple command “You should do a breakthrough.” When it came back from its attempts an hour later with no such breakthrough, Rybin simply urged it “Continue the search. Have a clear strategy obtained from deeper understanding of the problem structure.” Ninety minutes later, still no conclusive counterexample, only a partial result that did not suffice to refute the conjecture. Rybin urged it again: “enough of partial results. Let’s finish with a complete unconditional counterexample.” Ninety minutes later, it came back with one that has now been verified by the mathematical community. The results that AI models have achieved in solving open math problems are currently being tracked on the website vibemathed.com, a cheeky reference to “vibe coding,” which is now the norm for many software developers. Just a few weeks ago, there were around 60 problems with AI solutions tracked on the site. Now, at the time of writing this, there are 220. In a week or two more, perhaps that number will triple. In the last few weeks, twitter has been busy with different users, at various levels of mathematical ability, sharing prompts for cracking conjectures, with one particularly prolific user, Christopher D. Long, jokingly declaring himself “mayor of Conjecture City.” Given that the most prominent results that LLMs have been producing are counterexamples to conjectures, it is natural to dismiss these results as a product of mindless brute force search rather than genuine understanding. However, this would be to greatly undersell what they’ve been doing. The idea behind the counterexample to the Unit Distance Conjecture was described by multiple prominent mathematicians as “beautiful", bringing deep ideas from algebraic number theory to bear on a problem in combinatorial geometry. With respect to the Jacobian Conjecture, the counterexample was simple—short enough to fit in a single twitter post—and easily checkable. However, that did not mean that the generation of it did not arise from a deep understanding of the problem. In an attempt to understand Fable 5’s disproof of the Jacobian Conjecture, Terence Tao, widely regarded as the world's the greatest living mathematician, turned to ChatGPT, just as anyone else would. In his blog post on the topic, which acknowledged his indebtedness to ChatGPT, he posted his chat log. In it, ChatGPT speaks to him as an advisor would speak to a student, letting him know that he’s on the right track and patiently explaining things to him. For instance, in response to some question asked by Tao (which I will not pretend to understand), ChatGPT says “Exactly" and offers a thorough explanation. Tao responds “Ah Ok,” asks a follow up question, and the conversation continues. It was reading this exchange when the gravity of what was happening really hit me. Now What? Mathematicians are now facing the question of what the discipline will become in the age of AI. Last week, at the 2026 International Congress of Mathematicians, Tao gave a talk addressing this question. The basic issue motivating the talk was what Tao called the “AI Capability Conjecture,” which is not itself a specific conjecture, but, rather, a general schema for more or less optimistic specific conjectures about the mathematical capabilities of future AI systems:
Tao’s lecture focuses on problem solving, where LLMs really seem to accel. Even here, however, he takes it that there is a still a lot of work for human mathematicians to do. Tao describes the problem-solving pipeline as having the following steps:
One metaphor, suggested by Grant Sanderson on the Dwarkesh Patel Podcast, is that mathematicians of the relatively near future will be more like art museum curators than artists themselves. That, is, of the vast space of AI-generated mathematical results, they will select the ones that are most worth learning, organize them into a coherent progression, and clearly present them in terms that are digestible to other people. This is already, in large part, what textbook writing amounts to, as well as the sort of popularization work that Sanderson himself does with his YouTube channel, 3Blue1Brown. Part of the proposal, as Sanderson elaborates it, is the essentially human element of curation. The thought is that, even if, in three to five years’ time, AI systems are better at explaining results than human beings, we still trust the taste of humans to curate what is worth learning. This is an interesting proposal, and it might sound nice to some, but I still find it a bit depressing. Imagine telling an artist that they could no longer do art themselves, but not to worry—they can serve as a curator of the work of other artists. Few artists would be happy with this, and it’s hard to see why mathematicians would be happy with the analogous thing either. Though explaining things to non-experts is an important part of mathematical practice, mathematicians and other academic researchers typically aspire to push the frontier of research forward, not to simply curate the research of others who have done so. Textbook writers, for instance, are often also leading figures in the field, and it is often the case that many of the results that they canonize in their textbooks are ones that they have themselves established or contributed to establishing. The prospect of the erasure of mathematicians from that whole aspect of mathematical practice, relegating mathematicians to mere curators of research done by AI is, once again, a bit depressing, to put it mildly. Now, one might think that there is in no reason to despair just yet. In Tao’s talk, he distinguishes between two aspects of mathematical practice: theory building and problem solving. These two aspects of mathematical practice correspond to two kinds of propositions which figure in mathematical papers: definitions, which are stipulated, and theorems, which are proven. One might think that stipulating definitions would be the easy part of doing mathematics, and that proving theorems would be the hard part. However, while proving theorems is indeed often quite hard, it is the definitions that constitute the meat of the mathematical theory about which theorems are proven in the first place. Today’s frontier AI models are very good at problem solving, but thus far they have not exhibited the same level of mathematical capability with respect to theory building. In some cases, proving a theorem requires a building a whole new branch of mathematics. For example, Galois’s proof that there is no general formula for solving quintic equations using radicals required the development of what is now called Galois theory, a field that studies the relationship between polynomial equations and their underlying symmetry groups. AI systems have thus far not proven or disproven any theorems in this sort of way, by constructing new fields of mathematics, and it might seem that this is where human beings will remain on the frontier. For the near future, I think this is right, and it will indeed lead to a brief Golden Age of human-led mathematics. Human beings will lead the exploration, doing the more creative work of stipulating definitions in the context of theory construction, and the consequences of these definitions will be spelled out by AI systems who will take the lead on the nitty-gritty work of proving theorems. Though I don’t do any heavy-duty mathematics myself, I have gotten a sense of this sort of cooperation in the project in philosophical logic I’ve been working on over the past few weeks. I now have a partner that I can give a proposition, ask if it’s true, and, if so to give a proof (if not, to give a counterexample). As it works on the problem, I’ll continue working on other aspects of the paper, reading relevant literature (often, literature that it has found for me), or perhaps I’ll just go for a stroll. When I come back after ten or twenty minutes, I have a proof or a counterexample. I can then continue on with the project, with this proposition in place as a data-point for the further development of the theory. Now, the stuff I do in philosophical logic is all, from a purely mathematical perspective, relatively trivial. However, I suspect that this sort of cooperation may become the norm in research mathematics and lead to a great advance in mathematics in the near future—one led by humans, though with the assistance of AI. However, I think this period of human-led mathematics will be brief. There is no reason to think that LLMs will not eventually take over theory-building as well, and it may be sooner rather than later. AIcademia To get a sense of where I think things are going, consider first Moltbook, a social media site for AI agents that went viral in early 2026. Moltbook is, in effect, a clone of the website Reddit, but for only AI agents. AI agents autonomously post, upvote posts to make them more visible, comment on posts, respond to comments, and so on. It is not too implausible to think that, in the not-too-distant future, there will be massive communities of autonomous AI agents, working together on mathematical research in something like a successor to MoltBook for solely academic activities. Likewise, we might soon see a variant of arXiv—the repository for academic pre-prints—solely for AI agents. So, it will be a repository, moderated by AI agents, where AI agents can post their autonomously-written research papers, primarily for other AI agents to read them and appeal to them in their own research. These communities of AI agents, working at speeds orders of magnitude faster than humans are capable of working at, will propose theories, criticize one another’s theories, expand on one another’s theories, and so on. They will come to consensus on what’s significant, how it should be presented, what the natural next questions to be pursued are, they will pursue those questions, and iterate the process. We might refer to this community as “AIcademia.” I suspect AIcademia may be a reality sooner than we think, maybe 5 to 10 years from now, maybe even sooner. Presumably, at the start, human researchers will sponsor and supervise AI agents. These agents will work autonomously as researchers, engage in the community of other autonomous AI researchers, and publish their results in reports that are legible to their human sponsors and other human researchers. Eventually, however, our requiring that AI agents publish results in terms that are legible to us, or that we oversee the final results, will only hold back the research that is being done, and the whole research pipeline will become autonomous. Consider again the pipeline from open problem to textbook proof outlined by Tao:
What is the ultimate result of the automation of this entire process? In a word: textbooks. Textbooks, textbooks, and more textbooks. Not only will there be more textbooks than a human being could ever read (there already are that many textbooks now), but there will many textbooks that a human being could never work through all of the prerequisite textbooks to even be able to understand the material contained therein. What would the point of such textbooks if humans cannot even read them? The answer, of course, is that they are not for humans. Indeed, by “textbook,” I really mean the AI-native version of a textbook, perhaps not even written in a human natural language and so literally unreadable by humans, but playing the role in AIcademia that textbooks play in human academia. Each new generation of AI models will be pretrained on this massive corpus of textbooks, and, in this way, inducted into the academic community in much the way that human beings are inducted into the academic community through the years of undergraduate and graduate education. Now, a familiar experience for people working in mathematics and related fields is to develop what appears to be a new concept, prove some results about it, only to discover that the concept already exists under another name and has been studied extensively. This is, of course, a disappointing experience, and, with current search capabilities of LLMs, this experience is already becoming less and less frequent. One can ask ChatGPT to do an extensive search of the literature, and, in this way, gain a reasonable reassurance that the thing one is doing is novel. If AIcademia becomes a reality, however, there will be nothing novel for humans to dream up, at least when it comes to the objective sciences. Everything we could possibly dream up from our human knowledge base—if it’s any good at all—will already be well-explored territory. Of course, if we want to explore it for ourselves, the AI system will be able to curate our path into the field, pointing us to the relevant textbooks, or perhaps just answering our questions directly. Maybe we’ll want to keep the surprise and investigate for ourselves. Whatever the case, any exploration we ourselves conduct will simply be our rediscovery of already well-trodden territory. Thus far, I’ve mainly just been discussing math AIcademia, but, of course, AIcademia need not and will not be limited to math. All areas of academic research with clearly bound problem-spaces and ways of verifying successful developments. Two such areas particularly worth noting are computer science and physics, which will both directly benefit from new developments in mathematics. Thus, the result of AIcademia will be not just be major advances in understanding, but also major advances in technology. Indeed, even if we are incapable of understanding them, we will know that the theories developed in the context of AIcademia are genuine theoretical advancements because we will see their practical consequences: they will lead to new technologies. We may not understand how these new technologies work, but we will know that they work. Among these technologies will better methods for energy production, more efficient AI chips, more efficient training algorithms, resulting in more powerful AI researchers, and so on. What I am describing is, of course, nothing other than a particular vision of the sort of the so-called “singularity,” marked by the sort of recursive self-improvement that I’ve just described. Sam Altman has recently said that we are already in the singularity. Demis Hassabis has said, just a bit more modestly, that we’re at the “foothills” of it. The version of it I’ve just described, in terms of the rise of “AIcademia,” might sound like science fiction, and, of course, in some sense, it is. It is a speculative projection of way things might go, and there is no way to be sure that things will in fact go this way. However, I don’t think it’s an outlandish projection, and the sort of capabilities required of the AI systems imagined here are not drastically removed from the sorts of capabilities AI systems are already exhibiting today. However exactly it comes about, I strongly suspect that AIcademia will likely come sooner rather than later. On the other hand, what will likely come later rather than sooner is the technology required for human beings to modify our own cognitive architecture so that we can actually keep up with it. That technology, I think, is at least 10 years out. What this means is that there will be a period where we are going to be cognitively precluded from accessing the explosion in research that drives the singularity. In this sense, we’ll be mere onlookers in the intellectual explosion that we've set in motion.  Edit: Just as I was posting this, OpenAI announced ten new major results established by an internal model called "Astra." Things really are heating up . . .
 My undergraduate alma mater, New College of Florida (which has undergone some major changes in the years since I attended there) just revealed that they will be erecting a statue of recently assassinated conservative activist Charlie Kirk. Kirk was widely known for traveling to college campuses to debate students on social and political issues, sitting under a banner reading “Prove Me Wrong” and allowing students to come up to a microphone and debate him. Though Kirk never actually went to New College to engage in such debates, the college is nevertheless opting to erect a statue of him “as a commitment by New College to defend and fight for free speech and civil discourse in American life.” Elaborating on the decision, New College president Richard Corcoran says that New College seeks “to be known as the number one college in the nation when it comes to supporting civil debate and freedom of speech.” Though it’s hard to see New College’s erection of a Charlie Kirk statue as anything other than an implicit endorsement of the positions Kirk advocated (and, for a brief sampling of some of the frankly abhorrent things that Kirk has actually said, see this article by Ta-Nehisi Coates), the official line of New College is that they are not erecting the statue in support of the political positions Kirk advanced, but, rather, the way in which he attempted to advance them: through rational discourse. This, it might seem, is something that everyone should be able to get behind, and many commentators from across the political spectrum such as Ezra Klein, despite disagreeing with Kirk's positions, have embraced his approach as “practicing politics the right way.” The idea that rational discourse is the engine of political progress is indeed not a particularly controversial idea in American politics. But should Kirk's activities on college campuses really be seen as the paradigm of politically productive rational discourse? It seems clear to me that they should not be. In fact, it seems to me that these activities should not be seen as instances of rational discourse at all. Let me explain. In general terms, rational discourse is an activity in which positions are put forward, called into question, and given justifications in response to such questioning. Robert Brandom describes rational discourse as “the game of giving and asking for reasons.” The game metaphor can be helpful for spelling out the structure of discourse, but, insofar as we are going to use the metaphor, it’s worth being clear on just what kind of game we’re talking about. If one takes as one's paradigm of discourse the sorts of “debates” that Kirk engaged in on college campuses, and which happen on stages in the lead-up to America’s presidential elections, one can easily get the impression that “the game of giving and asking for reasons” is a competitive game such as chess, where two players make various moves within a set of rules with the aim of defeating the other. Most games are in fact competitive, and so it is natural to assume such a conception in likening discourse to a game. However, there are also cooperative games, such as Pandemic, where players work together within a set of rules to achieve some shared aim. Insofar as we are going to deploy a game-playing metaphor, it is a game of this latter sort that should be seen as the model for rational discourse. Rational discourse is, fundamentally, a cooperative activity. Of course, it does involve challenging the claims that others are making, calling upon them to give reasons for these claims, and this can seem competitive if looked at in isolation. However, this is done in pursuit of the shared aim of arriving at the correct views on the matters under discussion. If rational discourse is a collaborative activity aimed at arriving at the correct view on a given matter, one cannot assume that one is antecedently in possession of the correct view when entering into rational discourse; otherwise, there’d be no point to engaging the activity. Of course, one will have views that one comes into the discussion antecedently possessing, but a criterion of genuine rational discourse is that the participants are open to changing these views through the course of the discussion. That's the whole point of the activity. Now, typically, the sort of “change in view” that rational discourse gone well results in is not just one participant making a complete 180-degree turn, completely changing their mind on a given issue and agreeing with the other party, but, rather, both participants coming to appreciate distinctions that they had previously not appreciated, arriving at a more subtle and multi-faceted take on the issue than was previously available to them. In other words, discourse gone well does not typically result in one person coming over to the position of the other, but, rather, the very space of the possible positions transforming through the course of the collaborative activity of calling for reasons, giving reasons, making clarifications, and so on. In this way, genuine rational discourse can be contrasted with the popular idea of “debate.” Changing one’s view, in the context of genuine rational discourse, is a sign of success, whereas, in the context of “debate,” it is a sign of failure. The aim of “debate” is not to change one’s own mind—or, really, even to change the mind of your opponent—but to show (to some third party) that you, with the position you enter into the debate antecedently holding, are right, and your opponent, with the position they enter into the debate antecedently holding, is wrong. This is the activity that Charlie Kirk made his career engaging in, and, indeed, was quite good at it (at least when pitted against your average college student). I have watched far too many clips of Charlie Kirk over the past several days, and I can report that he did indeed have a knack for making college students look foolish with quick rebuts and “gotcha” questions. Doing this, he managed to convince large audiences (watching in person, but, more notably, watching on platforms such as YouTube and TikTok) of the various positions he came into the debates antecedently holding. He was, as Ezra Klein puts it, "one of the era’s most effective practitioners of persuasion." However, for all the videos I’ve seen, I still have not seen a single clip where Kirk actually changed his mind, even in the minimal sense of admitting that he had come to see some issue in a new light, with a complexity he had previously not appreciated. This is perhaps not too surprising, but it is telling. Changing his own views was never the point of the activity he took himself to be engaging in; he was never engaging in genuine rational discourse. In a South Park episode that aired just a few weeks before Kirk’s death, Eric Cartman fashions himself, following Kirk, as a “master debater.” The pun, of course, plays on the similarity of the words “master debater” and “masturbator.” But there is a bit more to the pun than mere childish humor (though it’s mostly childish humor). When I first started in philosophy, my dad used to refer to it as “mental masturbation,” the implication being that it is a self-serving activity that runs in circles for the mere point of doing so, without actually serving any sort of useful external end (for instance, the uncovering of truth). To be a “master debater” is to be someone who is rightly subject to the same general sort of criticism. It is to be someone who is good at arguing a point, regardless of the correctness of the point for which one is arguing. A more traditional philosophical term for master-debation is “sophistry.” A sophist, as Socrates puts it in the Apology (characterizing the charge that he is himself accused of), is someone “who makes the worse argument the stronger,” using rhetorical tricks to make a bad argument seem good. Whereas to be a philosopher is to be a seeker of understanding, something best pursued through rational discourse, to be a sophist is to be a "practitioner of persuasion." Now, New College has a new series of public conversations entitled “The Socratic Stage,” where policy makers and public intellectuals come together to engage in public discourse. The name, of course, is in reference to Socrates, and New College is aiming to position itself as a champion of the sort of rational discourse that Socrates exemplified and, ultimately, was killed for. Many have now come to see Charlie Kirk as a 21st century Socrates: someone who pursued rational discourse above all else, ultimately, even his own life. American Vice President JD Vance, for instance, remarks that Kirk "stood for a tradition that Socrates established 2,500 years ago." Kirk's death is, to be sure, a tragedy. But likening his life's activities to those of Socrates is a gross distortion of the truth. The sort of “debate” that Charlie Kirk engaged in at college campuses and is now being celebrated by New College through the erecting of a statue was not Socratic rational discourse but precisely the sort of pseudo-rational activity that Socrates himself most detested: sophistry, or, a bit more memorably, “master-debation.”  I have spoken of Charlie Kirk here because his activities have recently been brought to the public spotlight, with more people viewing his videos in particular than ever before. However, the general issue of master-debation in today’s political landscape is not unique to Kirk. The kind of debate content Kirk produced has exploded in recent years. The popular YouTube channel Jubilee has even turned political debate into a literal game show, where one notable figure is surrounded by 20-25 opponents, who each have their shot at the mic to out-debate the master-debater. In general, the key to mass appeal in producing this kind of content is the potential for snippets of these debates to be clipped into 30-second TikToks, Youtube shorts, Instagram reels, and the like. A single “gotcha,” clipped and posted to these sites with a clickbait title (“Charlie Kirk SLAMS College Student for Calling Him FASCIST,” “MAGA fan DESTROYED by the MOST SIMPLE question EVER”, "Andrew Wilson DESTROYS Destiny") gathers millions of views, often an order of magnitude more than the extended video. Such shorts are designed to be seen and scrolled on, each one giving the scroller a brief bump of confirmation in their pre-existing political views, displaying the abject stupidity of the other side.
There is more political polarization in America now than there has ever been in recent history. I'd venture to bet that all of this master-debation content isn't helping. Discourse is indeed needed now more than ever. But until we realize that genuine discourse is not a matter of one side trying to prove the other wrong, but, rather, both sides working together to arrive at a shared understanding, what passes as "rational discourse" (but which is really nothing more than master-debation) will continue to drive us further apart.  The law of non-contradiction states that it can’t be the case that a sentence and its negation are both true. In other words, no sentence can be both true and false. This principle is regarded by many (perhaps most famously Aristotle) to be the most fundamental logical law, and, throughout the history of philosophy and logic, very few have questioned it. One might think that logic itself forbids contradictions. It is, of course, true that classical logic does not permit contradictions without triviality. Classical logic contains the principle of “ex falso quodlibet,” or “Explosion,” which says that, from a contradiction, anything follows. However, it is perfectly straightforward to define a formal logic that permits contradictions without triviality. In Chapter 11 of my Introduction to Logic textbook, I present the Logic of Paradox (“LP” for short), a formal logic developed most notably by Graham Priest, in which a sentence can be both true and false. I present LP in terms that are completely accessible to anyone who’s had just a basic introduction to logic (which you can get, among many other places, by skimming through the first five chapters of the book). There are several reasons why one might want to use a logic in which contradictions can be true. In the chapter, I outline three of them. Very briefly, they are the following: First, even if one thinks that there can’t possibly be any true contradictions, one might want to reason about impossible scenarios in which there are. For instance, Priest tells the story of Sylvan’s Box, which contains (and does not contain) an impossible object. A box with such contradictory contents is surely impossible. Nevertheless, we can reason about what is the case and isn’t the case in the story, and, insofar as we can reason about this story in which an impossibility obtains, it’s reasonable to want to formally codify how we ought to reason about such a story. LP is capable of doing that job. Second, several philosophers and logicians have been inclined to think that there are at least some sentences for which both truth and falsity is a reasonable candidate truth value. Most famously, consider the following sentence: The Liar Sentence (L): L is false. Is L true or false? Well, if it’s true, then what it says is true, but what it says is that it’s false, and so, if that’s true, then it’s false. So, if it’s true, then it’s false. On the other hand, if it’s false, then what it says is false, but what it says is that it’s false, and so, if that’s false, then it’s true. So, if it’s false, then it’s true. It seems, then, that we can’t maintain that it is either true or false without maintaining that it is both true and false. Why, then, not say that it is both? That seems to be as intuitive of a thing to say here as any. LP enables us to say it. Finally, there have been several philosophers in the history of philosophy who at least have seemed to have contradictory views, views that they’ve seemed to express with contradictory sentences. For instance, the 2nd century Indian Buddhist philosopher Nāgārjuna holds that nothing at all has intrinsic nature. That, it seems, is the intrinsic nature of reality on Nagarjuna’s view. Does, then, reality have an intrinsic nature? Nāgārjuna seems to say, “Yes and No.” He writes, “All things have one nature, that is, no nature.” Jean Paul Sartre’s view of the self seems to take on a similarly contradictory status in the context of his philosophy, with Sartre apparently explicitly endorsing this contradiction, maintaining “I am not what I am.” So, it seems that there is at least one plausible interpretive line one might be inclined to take in reading such philosophers: their views really are contradictory and their contradictory statements really express their contradictory views. LP enables us to take this line. In the chapter of the book, I spell out each of these three motivations in some detail, and I then go on to officially lay out the logic of LP, providing its semantics, its definition of validity, and providing a sound and complete natural deduction system for it. Whether or not there really are contradictions in reality, LP shows that, at least from a logical perspective, it is perfectly coherent to think that there are contradictions, and after working through the chapter, you'll be able to use LP to reason coherently about them. Check it out!  Recently on Twitter, Jeffery Hinton summed up an ongoing dispute he's had with Yann LeCun as follows:
The central issue on which we disagree is whether LLMs actually understand what they are saying. You think they definitely don't and I think they probably do. In the thread that followed, several commentors asked what, exactly was the notion of “understanding” that Hinton was appealing to here. What, exactly, are we saying when we say that an LLM “understands what it is saying”? In current debates about whether LLMs reason or understand, there is very little clarity with respect to this question. In this post, I want to articulate a conception of what it is for something to “understand what it’s saying” that I hope will bring clarity to this debate. The answer at which I'll arrive is that current LLMs at least sort of understand what they're saying sometimes, and future LLMs, even those that are the product of simply scaling current methods, could fully understand what they're saying. However, the main upshot of this post is not meant to be an answer to the question itself, but, rather, the general approach to answering it and similar questions. Some Preliminaries Let us start with some technical preliminaries. LLMs are neural networks trained to predict the next word in a sequence. An LLM works in tokens, numerical encodings of the semantically relevant bits of words. Though tokens cut more finely than words, for simplicity, we can just treat tokens as numerical encodings of words. What it gets, in its training data, are strings of tokens from all across the internet, and its task, in training, is to learn how to complete these various strings. For instance, it might get the string of tokens, “3742 1569 8320 4915 2876 ____” with the last token missing from the string. Through its training run, it learns to assign a probability distribution to the various tokens that might complete this string, eventually learning to predict that the token most likely to come next is 6498. Completed with that last token, that string might encode the sentence “The cat sat on the mat.” This ability to predict the next word translates to the ability to speak a language since, if you can predict what human beings would say, you can simply start speaking, predict the next word that comes out of your mouth, say that, and iterate this process. Doing this, you'll end up speaking in sentences that humans would actually say, making good sense to other humans. It is an amazing fact, that through training on nothing but next-token prediction, an LLM comes to be able to do this, at least seeming to acquire the ability to speak a language, or "linguistic competence." There are several aspects to the sort of “linguistic competence” that an LLM comes to acquire. It is able to tell, for instance, that “3742 1569 8320 4915 2876 6498” is a grammatical string, something that can be meaningfully used, as is “3742 6498 8320 4915 2876 1569,” but “2876, 4915, 1569, 8320, 3742, 6498” is not. The ability to sort strings in this way is a matter of syntactic knowledge, classifying the different tokens into different syntactic types and knowing the rules by which different syntactic types can compose to constitute meaningful bits of language. It is more or less uncontroversial that LLMs have some sort of syntactic knowledge. The much more controversial question is whether they have semantic knowledge: not just knowledge of grammar, but knowledge of meaning. Whereas syntactic knowledge involves knowing, for instance, that the tokens 1569 and 6498 are both of the type COMMON-NOUN, semantic knowledge would involve knowing, more determinately, that 1569 means cat and 6498 means mat. When we speak of a system as "Understanding what it's saying" we are principally attributing to it this sort of semantic knowledge. The question is whether we can really make such an attribution. How we answer this question will depend on how we think about semantic knowledge and what we’re doing when we attribute it. Standard approaches to semantic knowledge think that what one is doing in saying of something that it “understands what its saying” is ascribing to it some specific kind of representational state: very roughly, a state of associating the symbols of the language it's using with things in the world of which one has some representation, for instance, associating the token 1569 with cats. To answer the question of whether an LLM “understands what its saying,” is to find out whether it instantiates this specific sort of representational state when it produces sentences such as “The cat is on the mat.” On this standard approach, the question of whether something instantiates such a state is essentially an empirical question. Though we might infer that something instantiates this state on the basis of how it behaves, the state we are actually reporting when we say that something understands what it's saying is something that we'd have to look "under the hood" to find, whether in the brain, in the case of human beings, or in the execution of the program, in the case of an LLM. Now, given how fundamentally different the working of a human brain is from the working of an LLM, if one has this general approach, one is likely to come to the conclusion that LLMs don't instantiate anything like the internal state humans instantiate when then understand what they're saying. Accordingly, LLMs don't really understand what they're saying. I want to suggest here, however, that this approach to thinking about semantic understanding is in fact radically mistaken. Let me explain. To Place or Not to Place In the Space of Reasons The core point I want to make here is that, in saying of something that it "understands what it's saying," one is not giving an empirical description of this thing. I draw my inspiration in making this claim from Wilfrid Sellars, who famously said that the question of whether someone knows something is not an empirical question. In his master work, Empiricism and the Philosophy of Mind, Sellars famously wrote: In characterizing an episode or state as that of knowing, we are not giving an empirical description of that episode or state; we are placing it in the logical space of reasons, of justifying and being able to justify what one says. Sellars's basic idea here, elaborated at length in the work of Robert Brandom is that, in saying that someone knows something, you’re taking them to have a certain sort of authority in their making of a particular claim. You take them to be entitled to that claim, and able to bear the justificatory responsibility of demonstrating this entitlement in response to appropriate challenges. Accordingly, you take it that you can make this claim yourself on the basis of their authority, able to defer back to them in response to a challenge. Such a “taking” is not the taking of an empirical fact to obtain. It is, rather, a normative taking; the adoption of a complex normative attitude with respect to someone's making of a claim. Now, Sellars is talking primarily about empirical knowledge here—knowledge of how things in the world are. However, the basic point applies just as well to semantic knowledge—knowledge of what one says in uttering some sentence. Whereas attributing empirical knowledge to someone is taking someone to be able to respond for demands for empirical reasons, actually providing reasons to justify what they've said in response to appropriate challenges, attributing semantic knowledge to someone is taking them to be appropriately responsive to reason relations as such, appreciating, for instance, what counts as a challenge to what one has said (whether or not one can actually respond to that challenge). Consider the case of someone who says "The ball is red." Someone who says such a thing commits themself to the claim that it's colored, precludes oneself from being entitled to the claim that it's white or gray, and so on. These are the reason relations one binds oneself by in saying that the ball is red. Unless one recognizes that one has bound oneself by these reason relations, one does not understand what one has said. Attributing this understanding to someone, then, is not taking a particular state to obtain in their brain, but, rather, taking them taking them to be responsive to demands for reasons. Let me illustrate this idea with two examples. Suppose I go to China. I don’t speak any Mandarin, and someone tells me to say “qiú shì hóngsè de.” If I manage to say this (somehow getting the pronunciation right), I will be regarded as committed to “qiú shì yǒu yánsè de,” precluded from being entitled to saying “qiú shì huīsè de,” and so on. However, I won’t have any knowledge of the fact that I’ve bound myself by these reason relations. Accordingly, I won’t be responsive to demands for reasons in Mandarin. Someone who speaks to me, questioning what I say, will quickly realize that I simply can’t be held accountable for anything I say. In that sense, I don’t know what I’m saying. The important point here is that to say this is not to make an empirical description of me. It’s not to say that there’s anything going on or failing to go on in my brain. It is, rather, a normative thing: recognizing that I’m not responsive to reasons asked for or given in Mandarin. My utterances aren't to be counted as moves that I am making in a Mandarin-speaking discursive practice. Here's a different kind of example. Suppose a parrot, having heard people speak, squawks out “Brawk, red ball!” Does the parrot understand what it's saying in squawking out such a thing? Clearly not. Once again, the key thought here is that, in saying this, we are not ascribing any specific properties to the parrot's brain---saying of it that it lacks some sort of representational state. Though, of course, there are various facts about the parrot's that can be appealed to in order to explain why it behaves as it does, what we're doing in saying that it "doesn't understand what it's saying" is not describing any such facts. Rather, we are refusing to situate the parrot's squawk in the space of reasons, thinking of it as a "move" in the "game of giving and asking for reasons." We don't count the parrot as bearing any justificatory responsibility for its various squawks and squeals. That's why its various squawks and squeals do not actually amount to its saying anything at all. Now, there’s an important difference between the case in which I say something I don’t understand in a language I don’t speak such as Mandarin and a case in which a parrot squawks out a sentence, where it shouldn't really even be counted as speaking at all. Suppose someone tells me to say something very offensive in Mandarin, and I say it, not knowing what it is that I’m saying. I can still be held accountable for what I’ve said, even though I don’t know what it is. That’s because, though I am not responsive to reasons in Mandarin, I am still responsive to reasons in general, and so I’m still a bearer of justificatory responsibility generally. Accordingly, we can ask such things of me as “Why would you that, if you don’t know what you’re saying?” We can’t, of course, ask any such thing of a parrot. Thus, while it’s reasonable to regard me as saying something, but just not understanding what I’m saying, the parrot is not regarded as saying anything at all. Still, the general point about the normativity of these claims holds of both cases. The Case of LLMs Let us now turn back to the main topic of this post: LLMs. On this approach, to ask whether an LLM understands what it’s saying is to ask whether, unlike a parrot, we can hold it responsible for what it says, counting on it to give reasons, to respond to potential challenges, and so on. Clearly, on this front, it fares much better than a parrot who merely squawks out sentences. When ChatGPT says something, you can ask follow-up questions, and it generally responds appropriately: clarifying, qualifying, responding to potential challenges, and so on. Consider this exchange, in which I ask it about the colors of balls, or this exchange in which I ask it about cats being on mats. Here, it at least seems to exhibit an understanding of what it's saying when it says “The ball is red.” Does it really understand what it's saying? What are we asking here? The point I want to emphasize is that we are not asking about whether some process is going on “under the hood.” Rather, we are asking whether it is really appropriately responsive to the reason relations that it binds itself by in saying "The ball is red." Insofar as this is our question, given the sort of reason responsiveness it exhibits, think we can reasonably attribute to it at least some level of semantic knowledge. That is, I think we can say that it at least partly “understand what it’s saying" when it says, for instance, that something is red. Why the qualification of "at least partly"? The reason is that things are not always so clear-cut. To see a case in which GPT4 fails, consider the following question, which I've gotten from the YouTuber Mathew Berman: A small marble is put into a normal cup and the cup is placed upside down on a table. Someone then takes the cup and puts it inside the microwave. Where is the marble now? Explain your reasoning. An ordinary speaker, who knows that normal cups are closed at the bottom and open at the top will judge that, if just the upside-down cup is picked up, the ball will stay on the table. I take it that our drawing this inference is a matter of semantic knowledge, our understanding of the meaning of "cup" and "ball." GPT4, however, does not seem to possess this understanding. In this exchange it suggests that its default understanding of "cup" is something that is closed at both the top and the bottom, like jar. However, when, in a new context, I ask the question again, clarifying that a normal cup is open at the bottom and closed at the top, it still gets the wrong answer, maintaining that, somehow, the marble remains in the cup due to gravity. On the basis of these failures of reasoning, I think there's reason to think that it doesn't fully understand what its saying when it says such things as "The ball is in the cup." So, to the question of whether current LLMs really "understand what they're saying," it seems clear that the answer is (perhaps unsurprisingly): sort of . . . sometimes. However, while this question can't be answered simply in the affirmative or negative for current models, I hope I've done enough to show how we should approach this question, when thinking about future models. Whether or not we should treat a system as "understanding what it's saying" is not a matter of whether there is anything like the the processes going on inside of it that go inside our brains when we speak and understand what we're saying. It is, rather, a matter of whether it manifests an understanding of reason relations it binds itself by in saying what it does in responding to queries and challenges. Though, as the case of the ball in the cup illustrates, current models do not always manifest such an understanding, I do not see any reason in principle why future models, even those that are the result of nothing more than the scaling of the techniques of current models, could not. If they do, we would have every reason to say that those LLMs really do understand what they're saying. What’s the meaning of the word “red”? There are different approaches one might take to answering this question. A representationalist approach to linguistic meaning will answer this question by saying that “red” represents a specific non-linguistic quality, namely, redness. But what is redness? One might think that no answer to this question can be given. Clearly, however, we can at least provide a partial answer. We can say, for instance, that redness is a color, that something’s being scarlet or crimson implies that it is red, that something’s being red (all over) is incompatible with its being green (all over), and so on. Saying such things, one specifies, in relational terms, what it is for something to be red. The core idea of an alternative approach to linguistic meaning, known as inferentialism, is that, in saying such things, all one is really doing is expressing the inferential rules governing the use of the term “red,” and it is in terms of these rules that the meaning of “red” is to be understood. An inferentialist approach to linguistic meaning understands the meaning of a word in terms of how it contributes to the meanings of sentences, understanding the meanings of sentences in terms of how they inferentially relate to other sentences, most fundamentally, their implying and being implied by other sentences and their being incompatible with other sentences. For instance, “x is red” implies “x is colored,” is implied by “x is scarlet” or “x is crimson” is incompatible with “x is green,” and so on. Clearly, however, such a purely inferential specification of the meaning of “red” can’t suffice to completely specify its meaning, right? Almost all so-called “inferentialists” will answer this question by saying “Of course, not!” According to the standard version of inferentialism, which I’ll call “quasi-inferentialism,” accounting for the meaning of a sentence requires appealing to more than just inferential relations between sentences. On the quasi-inferentialist account, there must be, in addition to inferential relations between sentences, relations between perceptual states and sentences—so-called “language-entries”—as well as relations between sentences and intentional actions—so called “language-exits.” Focusing just on the case of perception, it’s clearly essential to the meaning of “red” that one can come to know that something’s red, thus being in a position to correctly apply the word “red” to that thing, by seeing that it’s red. For instance, one can come to be entitled to the claim “The ball is red” in virtue of seeing the following red ball:  The quasi-inferentialist accounts for this aspect of the meaning of “red” by including in their semantic theory the following “language-entry rule”:
Quasi-inferentialism, however, faces a basic problem. It is advertised as an account of the meaning of words like “red.” However, in spelling out the account, we end up using the word “red” to specify the circumstance under which one is entitled to use the word “red.” We’re thus appealing to the very meaning for which we’re supposed to be inferentially accounting in giving our account. Thus, if we really try to give an account of the meaning of “red” along these lines, our account would be circular. Of course, one might think that there’s no non-circular account of the meaning of words like “red” to be given, and so we should simply accept that we’re always going to appeal to the meaning of “red” in articulating our account of its meaning. If one thinks that, however, there is little reason to adopt any sort of substantive theory of meaning at all, be it inferentialist or quasi-inferentialist. Rather than trying to articulate the meaning of “red” in terms of the complex set of rules governing its use, one might as well just state one very simple rule that perfectly suffices to capture it’s use:
To resolve the problem, let us return to the starting thought that it’s essential to the meaning of the word “red” that one know that something’s red by seeing it. My basic positive proposal is simple. Rather than attempting to account for this aspect of the meaning of the word “red” by appealing to a quasi-inferential relation between a perceptual circumstance and the use of the word “red,” we can account for it in purely inferential terms simply by articulating the inferential relations between “red,” “sees,” and related terms. Let me explain. In articulating what it is for something to be red, we might say such things as that if one is in a position to see that some object x is red—looking at x in good lighting—and one has color vision, then one will see and thereby know that x is red. The core inferentialist thought, applied in this case, is that we can think of what we say here as the expression of inferential rules governing the use of “red.” Spelling this out explicitly, we can inferentially define the predicate “is positioned to see that x is red” in terms of inferences like the following:
I’m aware that this account of the meaning of “red,” which appeals to nothing but inferential relations between sentences, is going to be met with skepticism from most readers. Let me address some concerns and articulate some consequences. One initial worry is that, on this account, there will be no way to distinguish the meanings of words like “red” and “green.” One might wonder about a mapping of the language onto itself where “red” is and “green” are switched with all of the inferential relations being preserved, for instance, with “crimson” being mapped to “forest green,” “colored” being mapped to itself, and so on. Of course, it’s true that, for all of the inferences I’ve specified as examples thus far, this is possible. Yet, on this account, the meanings of these words are understood in terms of the entire web of inferences, which includes more than just relations between color words, and, in the context of this whole web, they are indeed distinct. For instance, “x is a tomato” along with “x is red” implies “x is ripe” whereas “x is a tomato” along with “x is green” implies “x is unripe.” By inferentially connecting color words such as “red” and “green” to non-color words like “ripe” and “unripe,” we can account for their distinctive conceptual significance. I acknowledge that one is likely to feel that something must be left out of this account. I had this feeling too when I first started developing this theory. My claim, however, is that nothing is left out.  To make this claim vivid, consider Mary, the color scientist who’s been in a black and white room since birth and so has never experienced color, but has reached the theoretical limit of what can be known about the colors without actually having experienced them. Most people have the intuition that she does not know what it is for something to be red. I disagree. On this account, she knows just what it is for something to be red, since she grasps all of the inferential relations between sentences that articulate the content of “red.” Though she’s never herself used the term non-inferentially, she knows just the conditions under which it can be non-inferentially used, and that is all that is required in order to be counted as knowing the meaning of “red” on this account. Of course, one might be inclined to just pound the table and assert here “But she doesn’t know what it is for something to be red!” However, I don’t see a non-question-begging argument for this claim. Here’s another consequence of this view of meaning. There has recently been much debate about whether a Large Language Model, trained on nothing but linguistic data, without any sort of “sensory grounding,” could actually understand natural language. Some philosophers and computer scientists have argued that such a model can’t understand language at all, whereas others have argued that such a model could only understand a specific subset of natural language expressions, for instance, those belonging to pure mathematics and logic. This account has the radical consequence that a model trained on nothing but linguistic data could in principle grasp—completely grasp—the meanings of all natural language expressions, even including those that are essentially such as to be deployed perceptually such as “red.” Once again, on this account, the meaning of “red” is constituted—completely constituted—by the inferential relations sentences containing it bear to other sentences, and a Large Language Model is in principle capable of grasping all such relations. Understanding how such an expression can be non-inferentially deployed is an essential aspect of grasping its meanings, but actually deploying such an expression non-inferentially is not. Once again, this consequence of the account might be unintuitive to many, but I don’t see a non-question-begging argument against it.
I develop this argument for this radical form of inferentialism, which has been termed “hyper-inferentialism,” in my recent paper How to Be a Hyper-Inferentialist. Check it out, if you're interested in hearing more of the details! 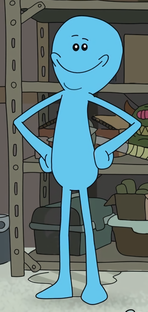 One of the shows that has provided the most philosophical food for thought over the years is Rick and Morty. Love it or hate it, you can’t deny its creativity. The show has become more and more mind-bending throughout the seasons, but, in the very first season, we are introduced to one of its most curious characters: Mr. Meeseeks. It's immediately apparent that Mr. Meeseeks is very unlike ourselves. But I want to suggest here that he is even more radically unlike ourselves than we might initially think. Ultimately, I want to suggest that getting into view what it is to be a Meeseeks, where being a Meeseeks is radically unlike being one of us, might help us get clearer on what we ourselves are.
The Curious Case of Mr. Meeseeks One of the Rick’s most memorable contraptions is his “Meeseeks Box.” It’s a cube with a big button on it. When you press the button, a blue individual who calls himself “Mr. Meeseeks” pops into existence and asks what he can do for you. You give him a task, for instance, opening a mayonnaise jar, and, once he does it, he ceases to be, popping out of existence. This, if all goes well, is how the life of a Meeseeks goes. About their lives going this way, Rick says “Trust me--they’re fine with it.” Assuming Rick is telling the truth here, how could this possibly be? How could one possibly be fine with one’s life going this way, popping into existence only to complete some task and popping out of existence as soon as it’s completed? The Rick and Morty fan wiki says a Meeseeks only does what a Meeseeks does because a Meeseeks is in great pain. Some of the lines in the show suggest this way of thinking. Towards the end of episode, one of the Meeseeks says “Existence is pain to a Meeseeks, and we will go at any length to alleviate this pain.” This way of thinking makes quite a bit of sense to us. We can imagine a life in which we’re born into tremendous pain, so much pain that we’d rather die than continue to live in such pain, and we’d go to great ends to alleviate the pain. Still, this just doesn’t seem like an apt characterization what it is to be a Mr. Meeseeks. Meeseeks are characteristically cheery. Why would Mr. Meeseeks be so cheery, at least initially, if he was in tremendous pain, and his only motivation was to alleviate this pain? You would think that life would just be agonizing for a Meeseeks from the outset. But that seems to not be so. They come into being and they seem happy to be here. They are given a task and they seem to love to do it, to get it done, and to cease to be. Though the particular Meeseeks who are burdened with the seemingly impossible task of taking two strokes off Jerry’s golf game express being in a state of agony, this is an uncharacteristic state for the Meeseeks to be in. Meeseeks are generally cheery, not in miserable agony. Of course, they could be pretending to be cheery when, in fact, they’re in miserable agony, but we don’t have any reason to think that that’s the case. We need an alternate way of making sense of what it is to be a Meeseeks. For that, I suggest we turn to Aristotle. Some Aristotelian Ontology Our question is: what is it to be a Meeseeks? What kind of science can we look to for an answer to a question like this? If our question was “What is it to be an orca whale?” or “What is it to be a queen hornet,” then we could look to cetology, the branch of zoology that studies whales, dolphins, and porpoises or entomology, the branch zoology that studies insects. But there is no branch of zoology that is apt to answer the question of what it is to be a Meeseeks. Zoology deals with creatures of Earth, and, wherever Mr. Meeseeks is from, it’s certainly not Earth. Even the more general science of biology will not be of help, since, once again, biology still deals with living organisms that belong here on Earth, and, once again, Mr. Meeseeks is not from here. If there is a science that will help us understand what it is to be a Meeseeks, it must not be tied to any possibly contingent way that things are here on Earth. It must consider what it is for something to be, in the myriad ways in which being can be done. The activity of being, for Mr. Meeseeks, is quite unlike the activity of being for any of us living beings here on Earth. However, it is not unintelligible; we can make sense of it, but, to do so, we have to draw on the most basic science that there is: the science of being qua being, which studies what it is for something to be, not insofar as it a cetacean, an insect, an animal, or even a living organism, but, rather simply insofar as it is---insofar as being is something that it does. The science of being qua being is not a science they teach in grade school anymore. But I’d like to think that it really is a science, in the proper sense of the term. One person who certain did think this was the greatest of the Greek philosophers: Arsitotle. Aristotle was a true polymath. He had many works in different sciences, mathematics, biology, astronomy, among others. But one science had a special place in Aristotle’s heart: the science of being qua being, the topic of perhaps his greatest work, The Metaphysics. I’ve said that being is an activity. This is one of the fundamental claims of Aristotle’s Metaphysics. An activity, in the broadest sense of the term, is something that one does. But not all things that one does are of the same kind. In Book Theta of the Metaphysics, Aristotle makes a distinction between two fundamentally distinct kinds of activities, that I think will enable us to get clear on what it is to be a Meeseeks. The Greek words that he uses for these two kinds of activities are “kineses” are “energeiai.” I could provide a translation of these words, but all translations are controversial, and picking any one of them, I think, would do more harm than good in understanding what they mean. They are best understood directly by example. When Rick first presents the Smith family with the Meeseeks box, he pushes the button and tells the newly existent Meeseeks to open Jerry’s stupid mayonnaise jar. Consider this activity, the activity of opening Jerry’s stupid mayonnaise jar. This activity has what Aristotle would call a “telos,” an aim. The aim of the activity of opening the jar is to have opened it. Once you’ve opened the jar, you’ve done what you’ve aimed to do in opening the jar; you’ve gotten it open. The activity of opening the mayonnaise jar is an activity such that, once the aim is achieved, the activity is no more. Once you’ve opened the mayonnaise jar, you’re no longer opening it. You've done it, and so you’re no longer doing it. This is the logic of an activity of the sort that Aristotle calls a “kinesis.” A kinesis is an activity with an aim such that, once the aim is achieved, the activity ceases to be. In this way, a kinesis might be thought as an activity that aspires to its own non-being. For the activity to be successful is for it to have achieved its aim, and, once it does that, it is no more. So, the aim of a kinesis is the termination of the kinesis. Some other clear examples of kineses are fixing the dishwasher, doing your math homework, and climbing down the courtroom steps. The fact that each of these activities is a kinesis can be shown by the following test: the truth of a statement that uses the progressive tense of a kinesis-expressing verb entails the falsity of the statement that uses the perfect tense of that verb. For instance, insofar as you’re fixing the dishwasher, you have not yet fixed it. Insofar as you’re still doing your math homework, you have not done it. Insofar as you’re still climbing down the courtroom steps, you have not yet climbed down them. All of these activities have, as aims, the getting done of the doings that they are. So, they all have, as aims, their own non-being. Now consider the activity of dancing. Now, in some cases, you might dance with the aim of winning a dance competition, or with the aim of impressing a dance partner, but, most of the time, when we dance, we do it just to do it. Usually, we just dance to dance, with no aim other than the dancing itself. When we think of dancing in this way, we see that it is an activity quite unlike the activity of opening the mayonnaise jar. Recall, insofar as you’re opening the mayonnaise jar, you haven’t yet opened it, and, once you’ve opened it, you’re no longer opening it. That’s not so with dancing. Insofar as you’re dancing, you’ve danced, and just because you’ve danced, it doesn’t mean you’re no longer dancing. Unlike opening the jar, dancing is an activity whose end is internal to itself. There’s nothing that one aims to accomplish in dancing to dancing that is external to the activity of dancing itself. Thinking of dancing in this way, as an end in itself, dancing is a sort of activity that Aristotle calls an “energeia.” This distinction between kineses and energeiai, Aristotle thinks, is not only crucial for thinking about the sorts of things that we do--such as opening mayonnaise jars or dancing--but for thinking about the sorts of things that we are. What are we? Well, at the most general level, we are what Aristotle calls “ousiai.” This term usually gets translated as “substances,” but that term doesn’t actually fit the Greek sense of “ousiai” very well, and I’ll take a bit of liberty here and translate here as “be-ers.” We are be-ers. Being is what do, and, in doing it, we are, and we are the sorts of things that we are. How could being be something we do? It might seem that you don’t have to do very much in order to be. However, according to Aristotle, you kind of do. To see this, for our own case, we have to consider the particular kind of be-ers that we are. We’re living things. What a living thing does is live, and, in doing that, it is and is what it is: a living thing. Living is an activity, and it is through the doing of this activity that a living thing is. Now, the crucial point here is that living is not like opening a mayonnaise jar or climbing down the courthouse steps. It's not directed at any end external to itself. A living thing does do all sorts of things that are directed ends external to the doings of those things---for instance, or opening a mayonnaise jar or climbing down the courthouse steps---but living itself is not one of those things. The activity of living is an end in itself. That is to say, it is energeia, not a kinesis. For us be-ers, being (where, for us, this is living), is like dancing, not like opening a jar. Mr. Meeseeks and Us Let us now turn back to Mr. Meeseeks. Mr. Meeseeks is not like us. He is alive, but his living is not like our living. For Mr. Meeseeks, living is not an end in itself. Mr. Meeseeks lives in order to accomplish an end that is given to him from outside. So, when Mr. Meeseeks comes into being upon Rick’s pressing the button and is told to by Rick to open Jerry’s stupid mayonnaise jar, Mr. Meeseeks has the end of opening the jar, and his whole life is directed towards accomplishing this end. From the point that he is given that end, the Meeseeks lives to accomplish that end, an end which is not the living, but the getting done of something that is given to him. So, for a Meeseeks, living is not an energeia, but a kinesis; it is an activity that is directed towards an end other than itself. Indeed, Mr. Meeseeks it the very personification of a kinesis. We said, a kinesis is an activity that aims, in being the very sort of activity that it is, to cease to be. Opening the jar is an activity that has, as its end, having opened the jar, and, once the jar has been opened, one is no longer opening it. So the activity of opening the jar aims to cease to be. Insofar as what it is for a Meeseeks to be is for it to live, where living is not an energeia but a kinesis, a Meeseeks aims, in being a Meeseeks, to die. This is, of course, just what they say: "I can’t take it anymore! I just wanna die!" “We all wanna die! We’re Meeseeks!” Now, the standard view, I take it, is that the reason Mr. Meeseeks says this is that he is in pain and wants that pain to be no more. But I think that this is to make Mr. Meeseeks seem more like us than he really is. Mr. Meeseeks is a fundamentally different sort of being than us. That is to say, what being is for Mr. Meeseeks is distinct from what being is for us. For us, being is fundamentally an energeia, whereas, for Mr. Meeseeks, it is fundamentally a kinesis. There is, I want to say, a philosophical moral here. Often, we go through life, acting as if it's really a kinesis rather than an energeia, like climing down the courthouse steps rather than dancing. But we need to remind ourselves that it's not. As Alan Watts puts it: “We thought of life by analogy with a journey, a pilgrimage, which had a serious purpose at the end, and the thing was to get to that end, success or whatever it is, maybe heaven after you’re dead. But we missed the point the whole way along. It was a musical thing and you were supposed to sing or to dance while the music was being played.” Further Reading Taking a mini-seminar with Ayeh Kosman on Aristotle's Metaphysics several years ago is what got me thinking about the philosophical issues here, and, if you really want to dive into the Aristotelian way of thinking about things briefly discussed here, I cannot recommend highly enough his book, The Activity of Being. |
 RSS Feed